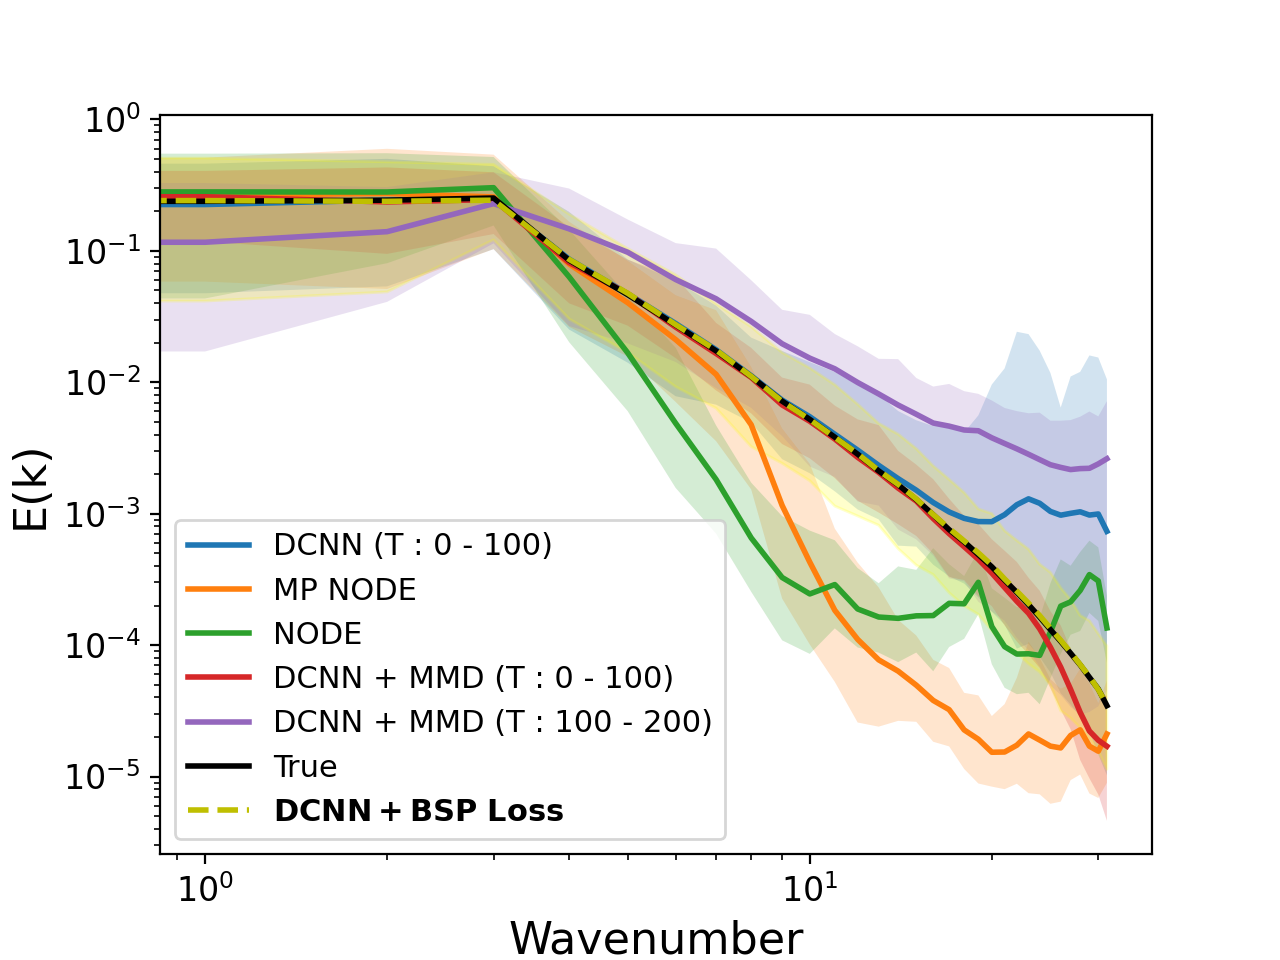
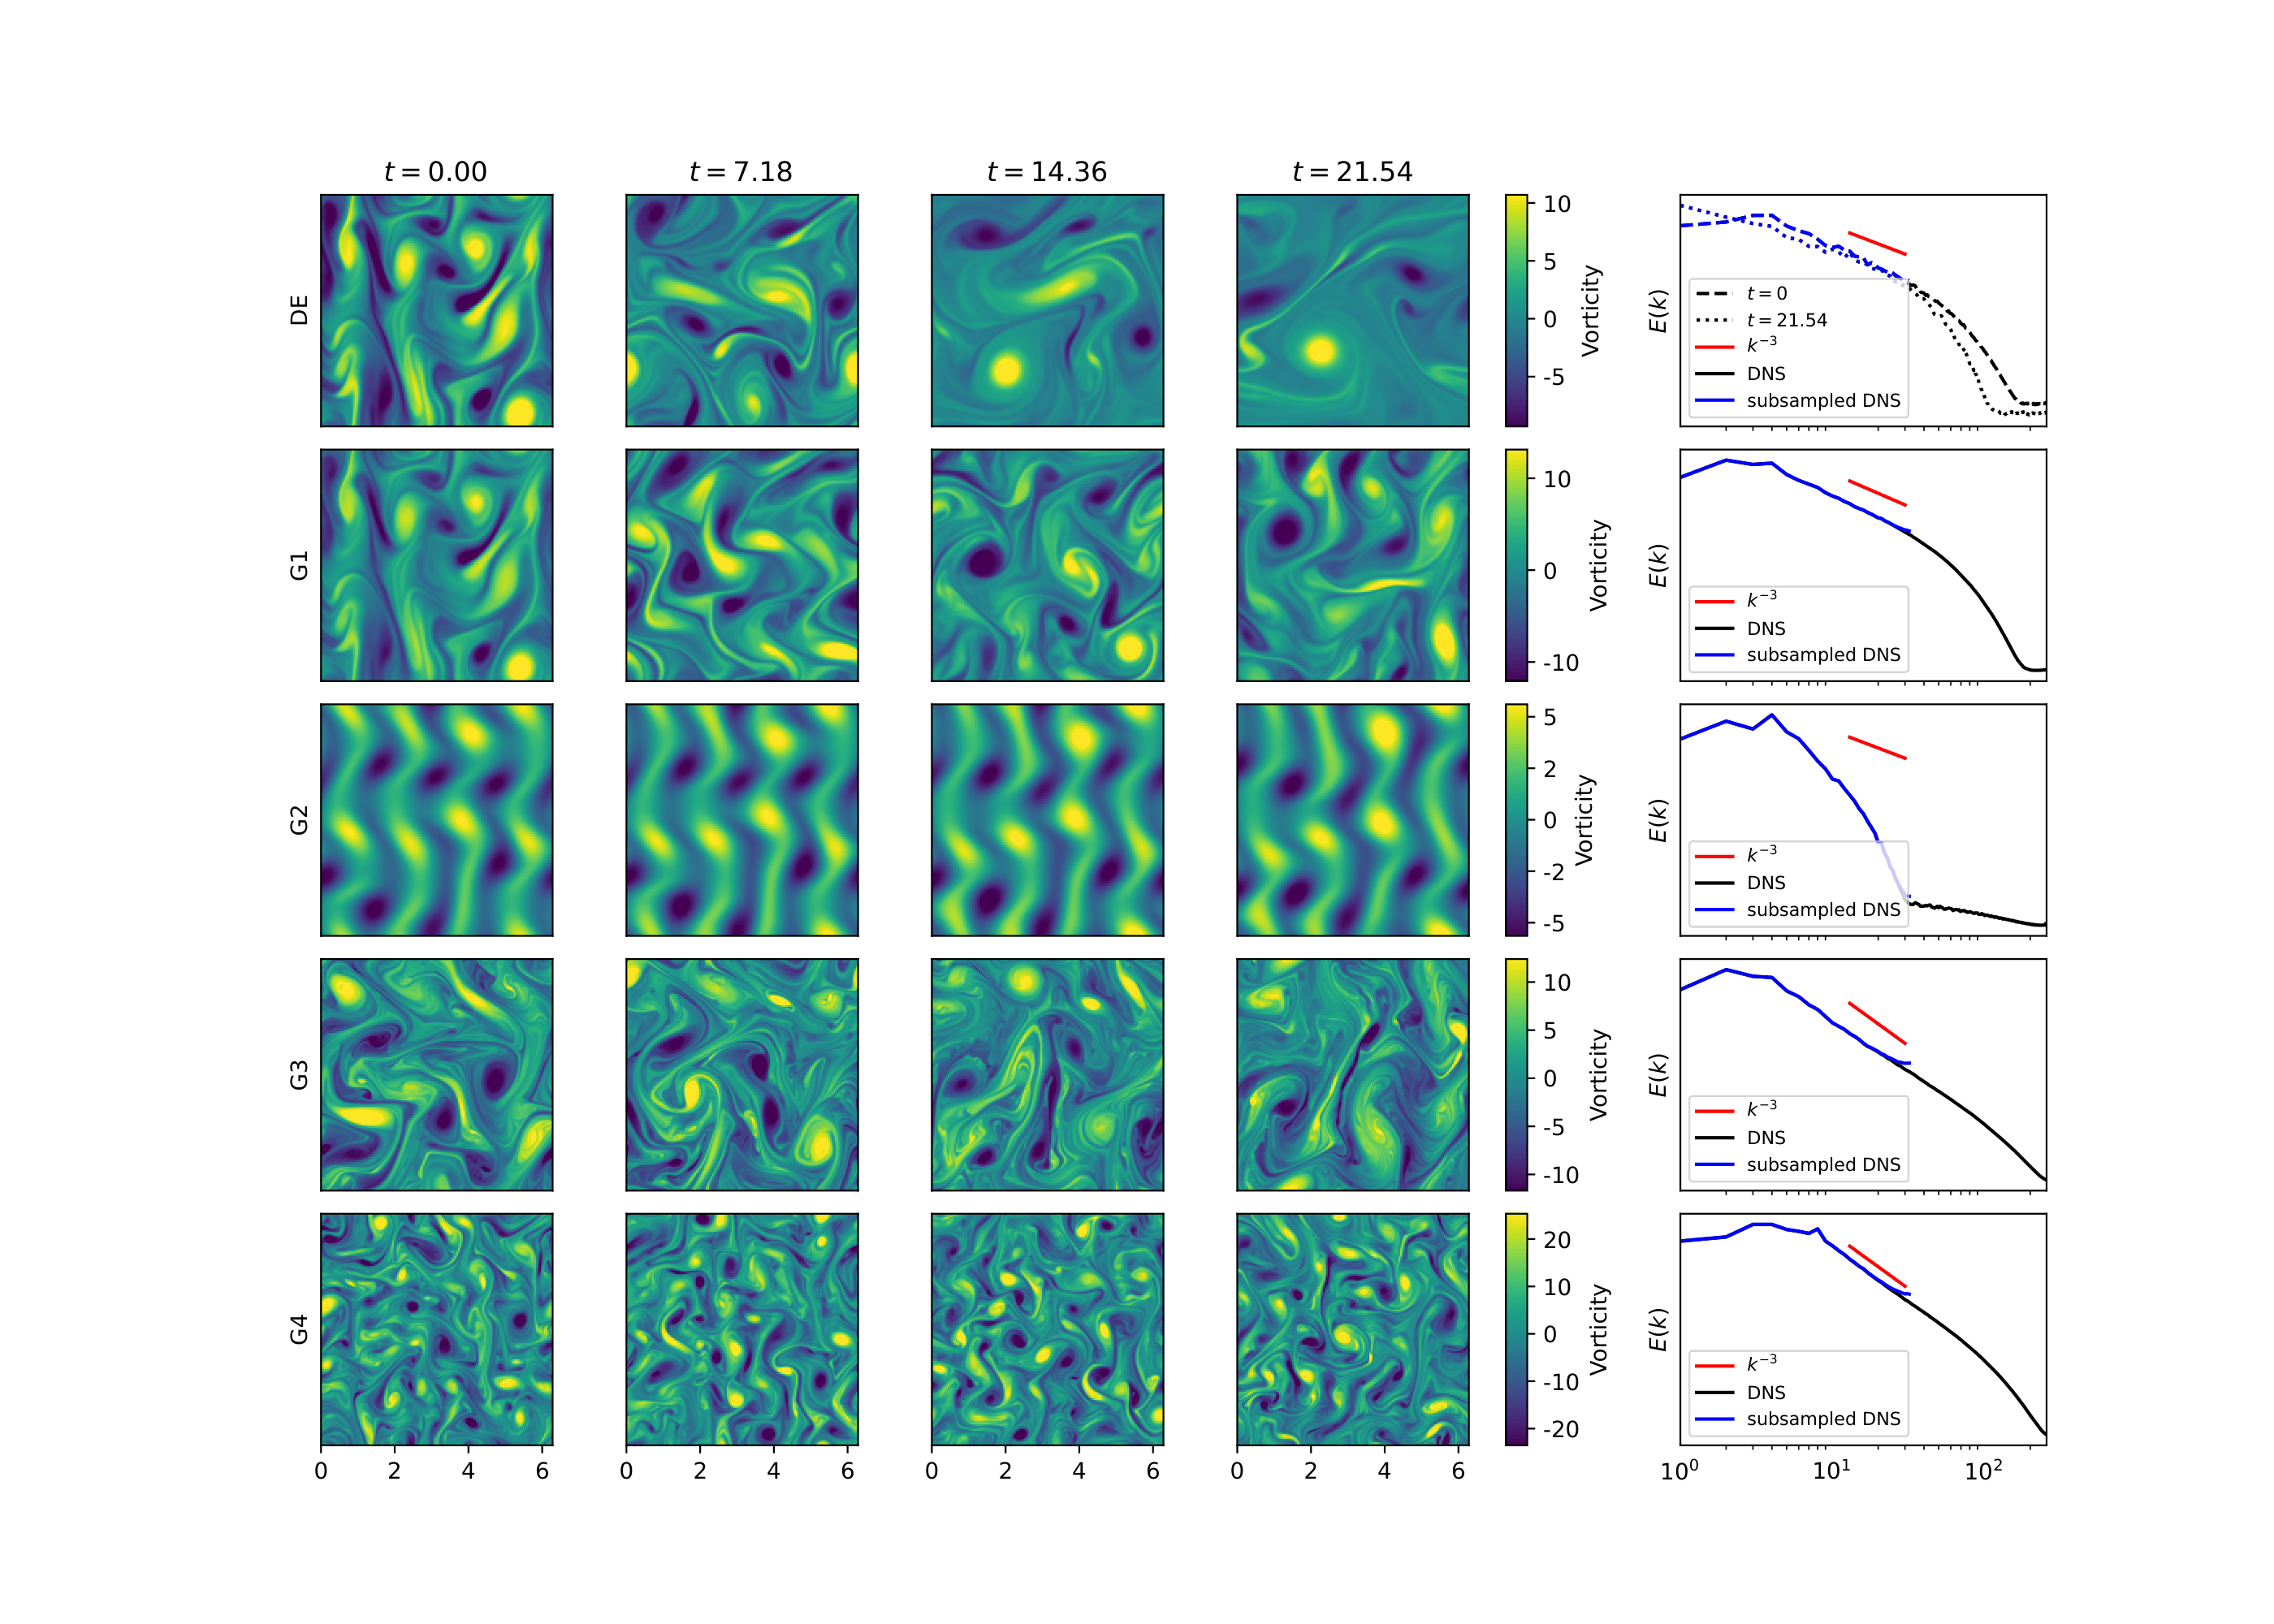
The paper starts from a common problem in chaotic forecasting: neural networks often fit
low-frequency structure more easily than high-frequency content, which leads to spectral
bias and poorer long-horizon predictions. To address that, it introduces a binned spectral
power loss that measures errors across frequency bands rather than only in physical space.
The reported result is more stable forecasting and better spectral fidelity on
high-dimensional chaotic systems and turbulent-flow benchmarks. The main conclusion is
that loss design alone can materially improve multiscale prediction quality without
changing the underlying network architecture.
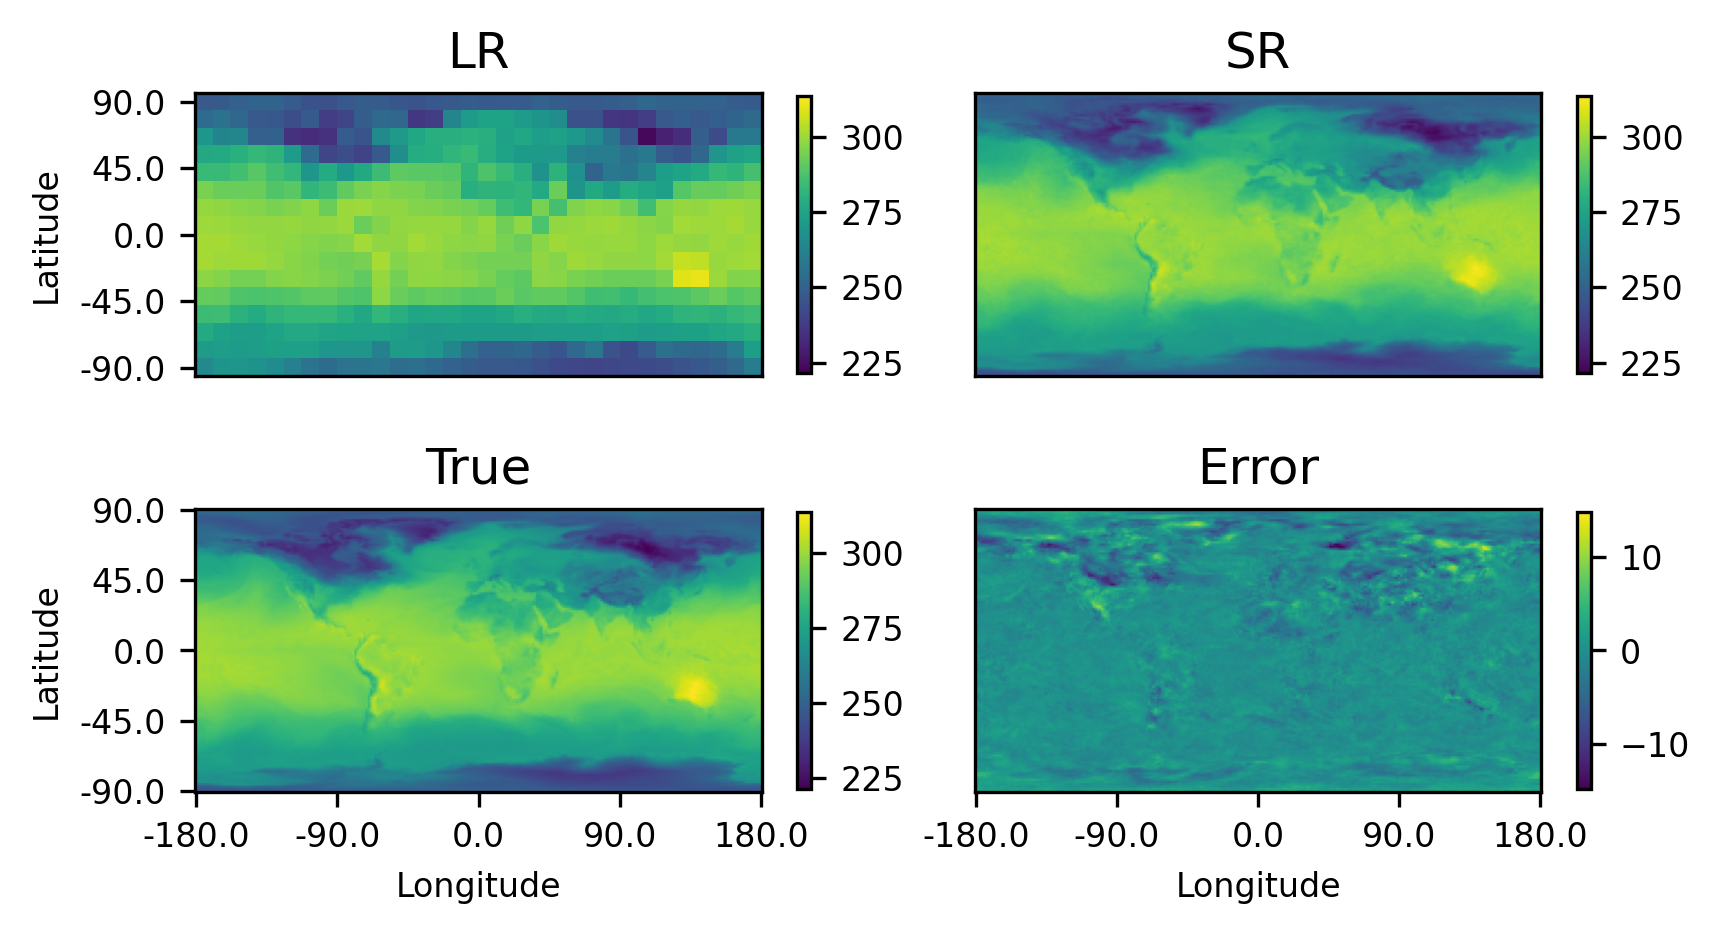
The background for this work is that atmospheric reconstruction often relies on coarse
fields or sparse observations, while downstream science needs sharper high-resolution
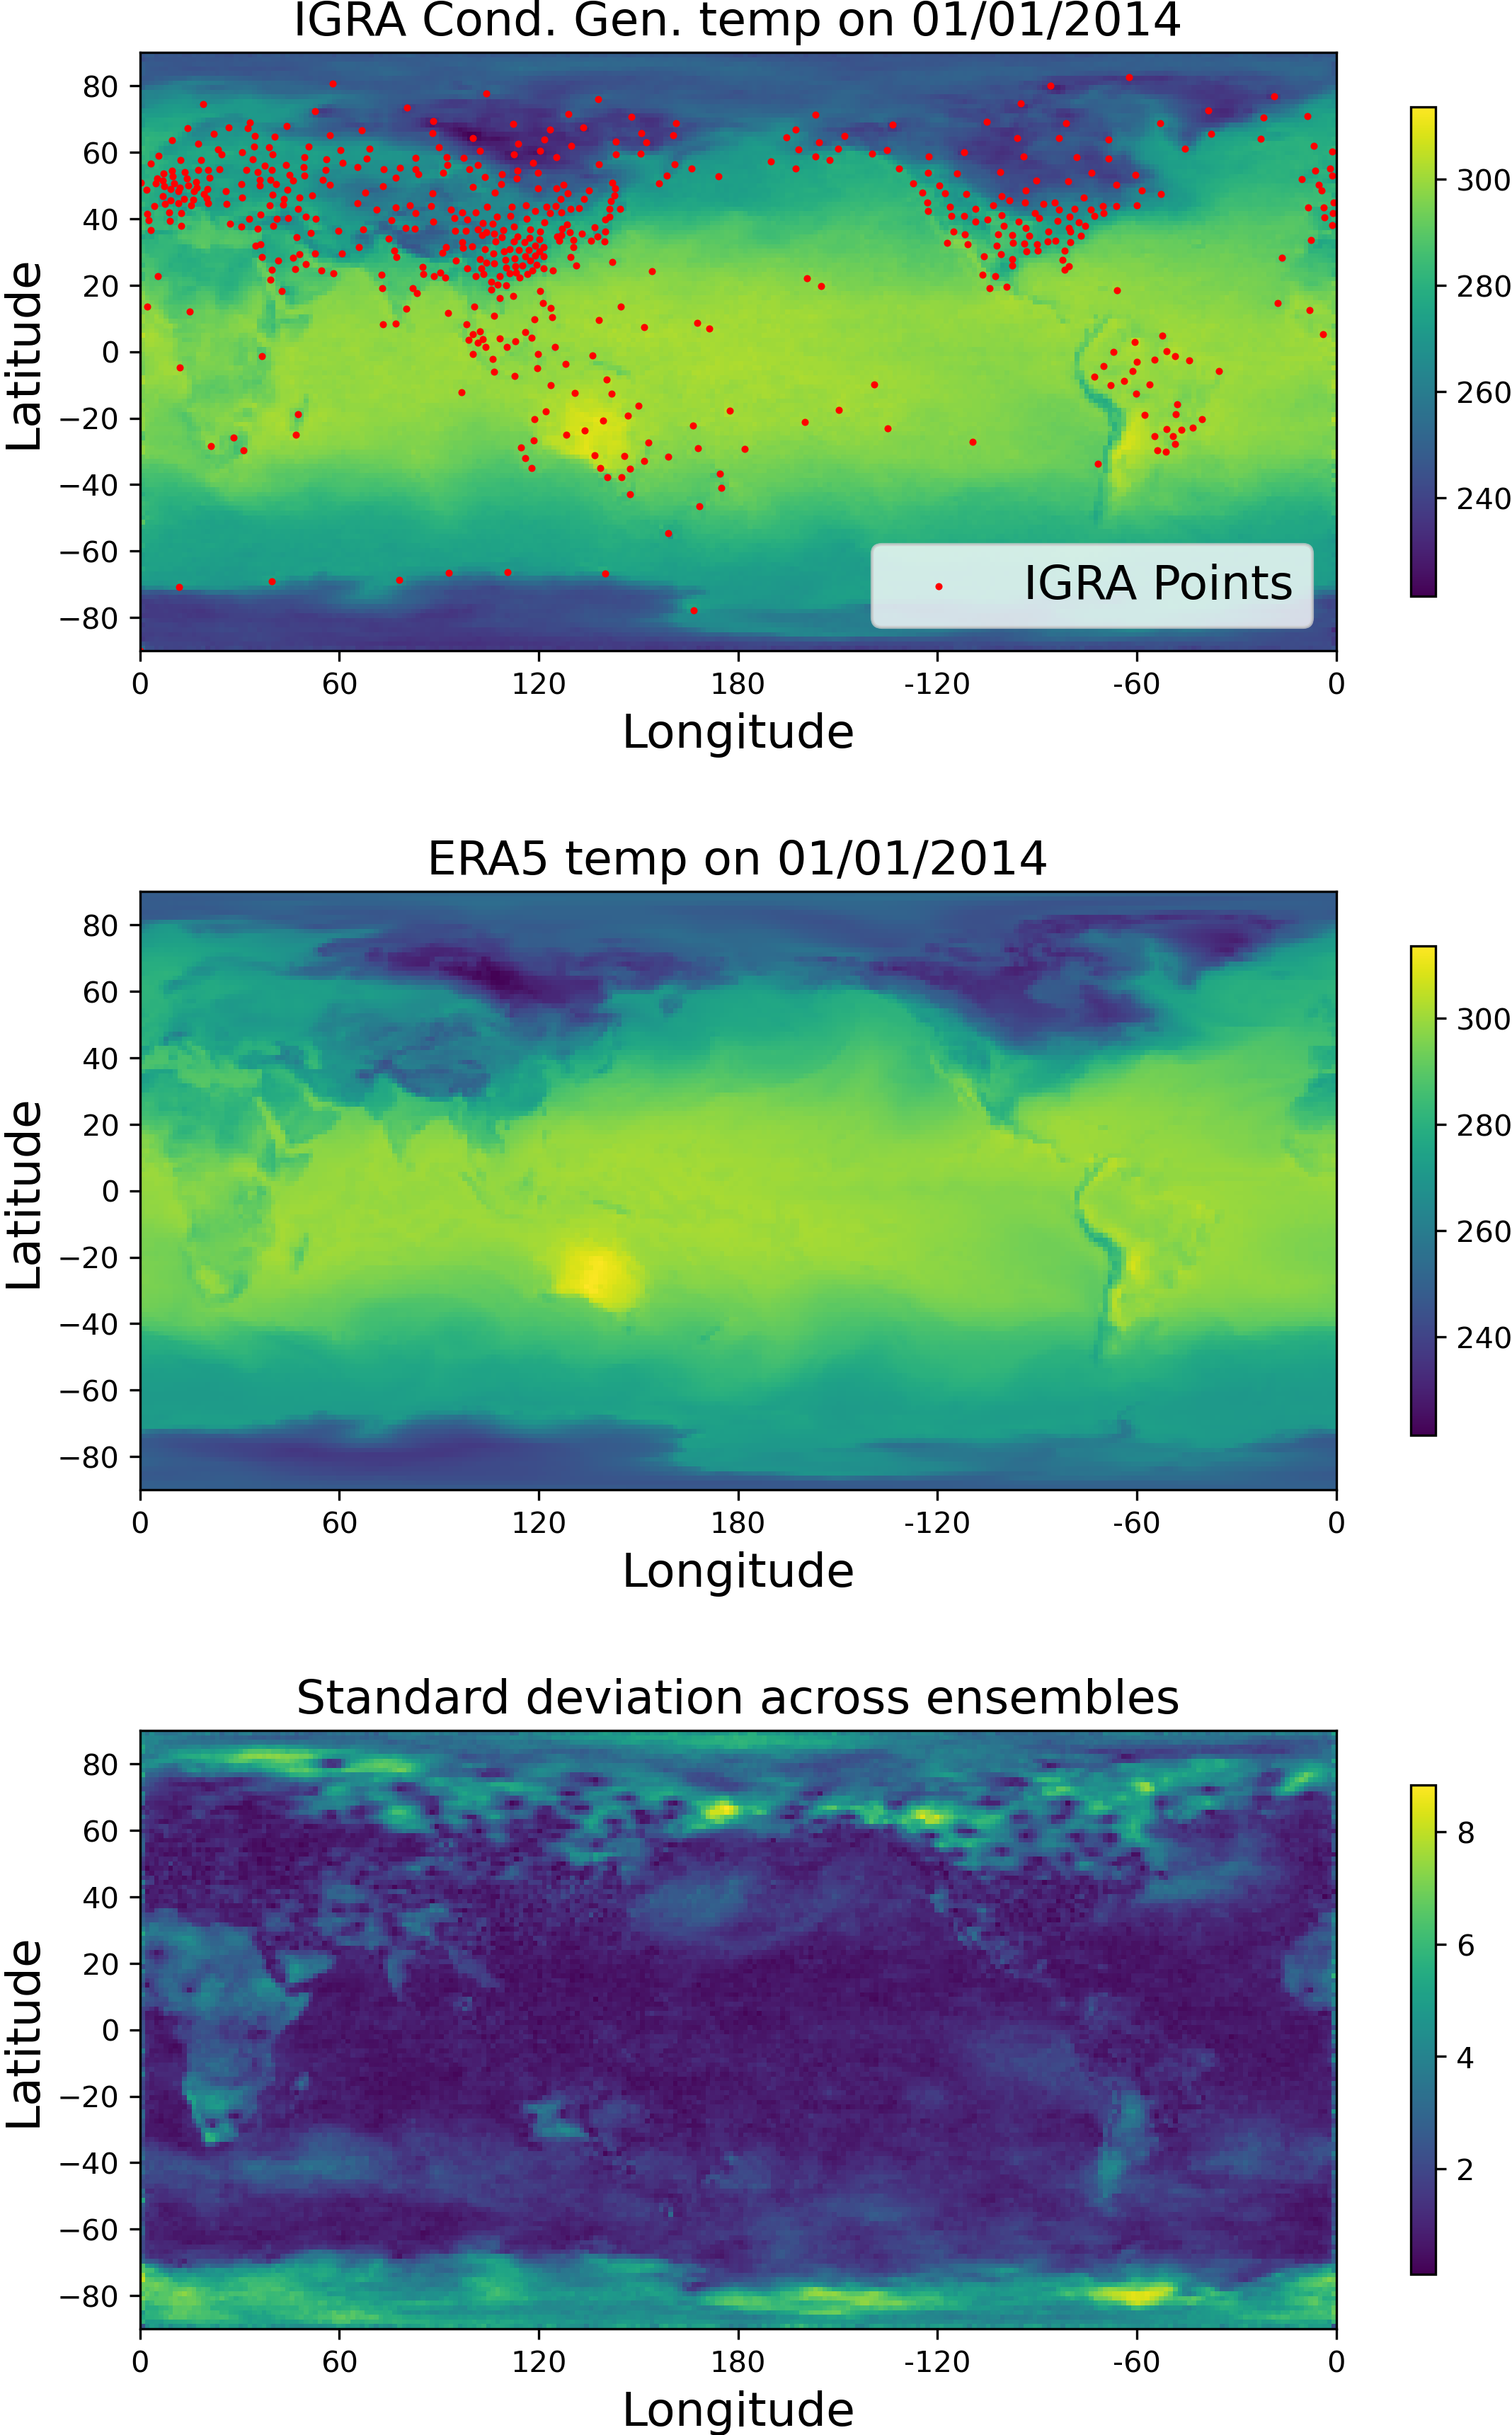
states. The paper uses score-based diffusion modeling to combine low-resolution inputs and
sparse sensor observations for atmospheric super-resolution.
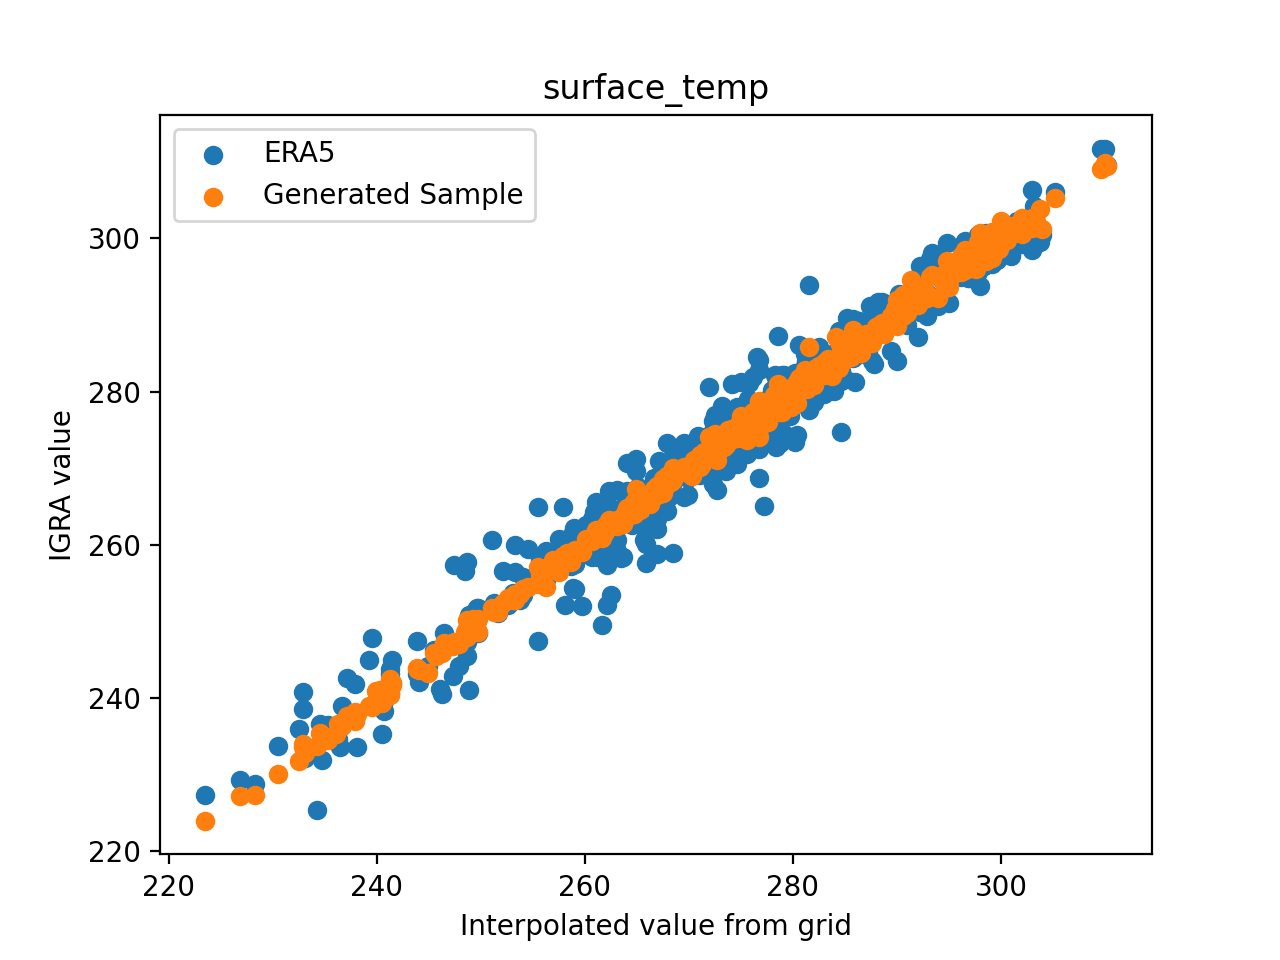
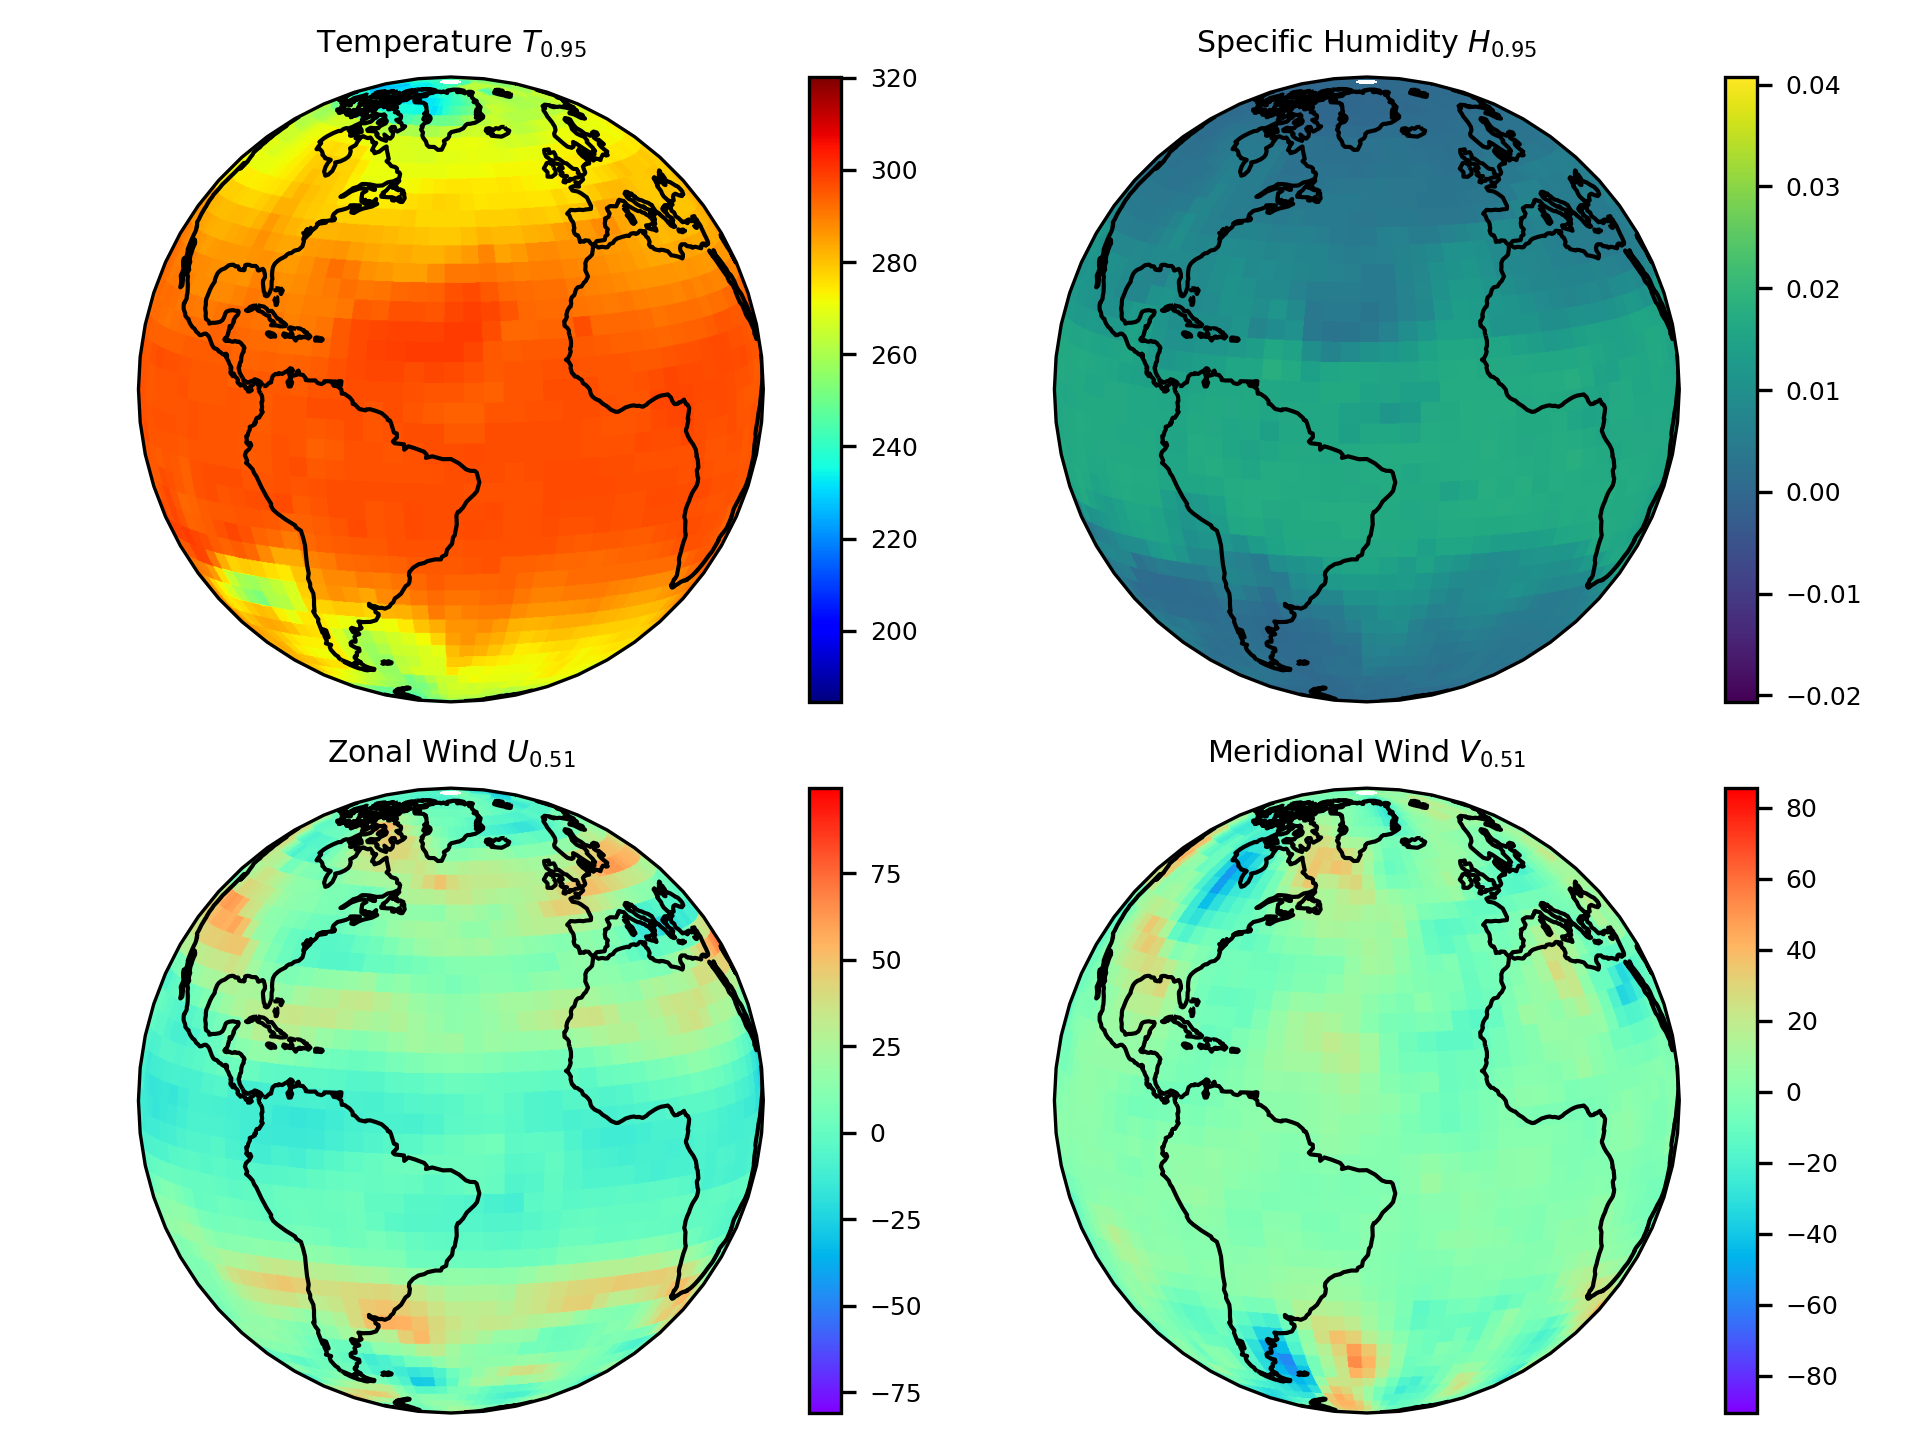
The results show reconstruction of ERA5 atmospheric states from coarse representations and
IGRA radiosonde data, together with uncertainty estimates. The main takeaway is that a
diffusion-based multimodal framework can fuse heterogeneous observations while preserving
fine-scale atmospheric structure.
This work is motivated by the difficulty of producing probabilistic long-horizon forecasts
for nonlinear turbulent systems while still being able to assimilate new observations.
The paper builds a diffusion-based surrogate forecasting framework with a multi-step
autoregressive objective to improve rollout stability over long time windows.
The reported results include probabilistic forecasting, adaptive sensor placement through
uncertainty or error-estimation modules, and data assimilation via diffusion posterior
sampling without retraining the surrogate. The conclusion is that generative surrogates
can support both forecasting and observation-driven correction in complex flow systems.
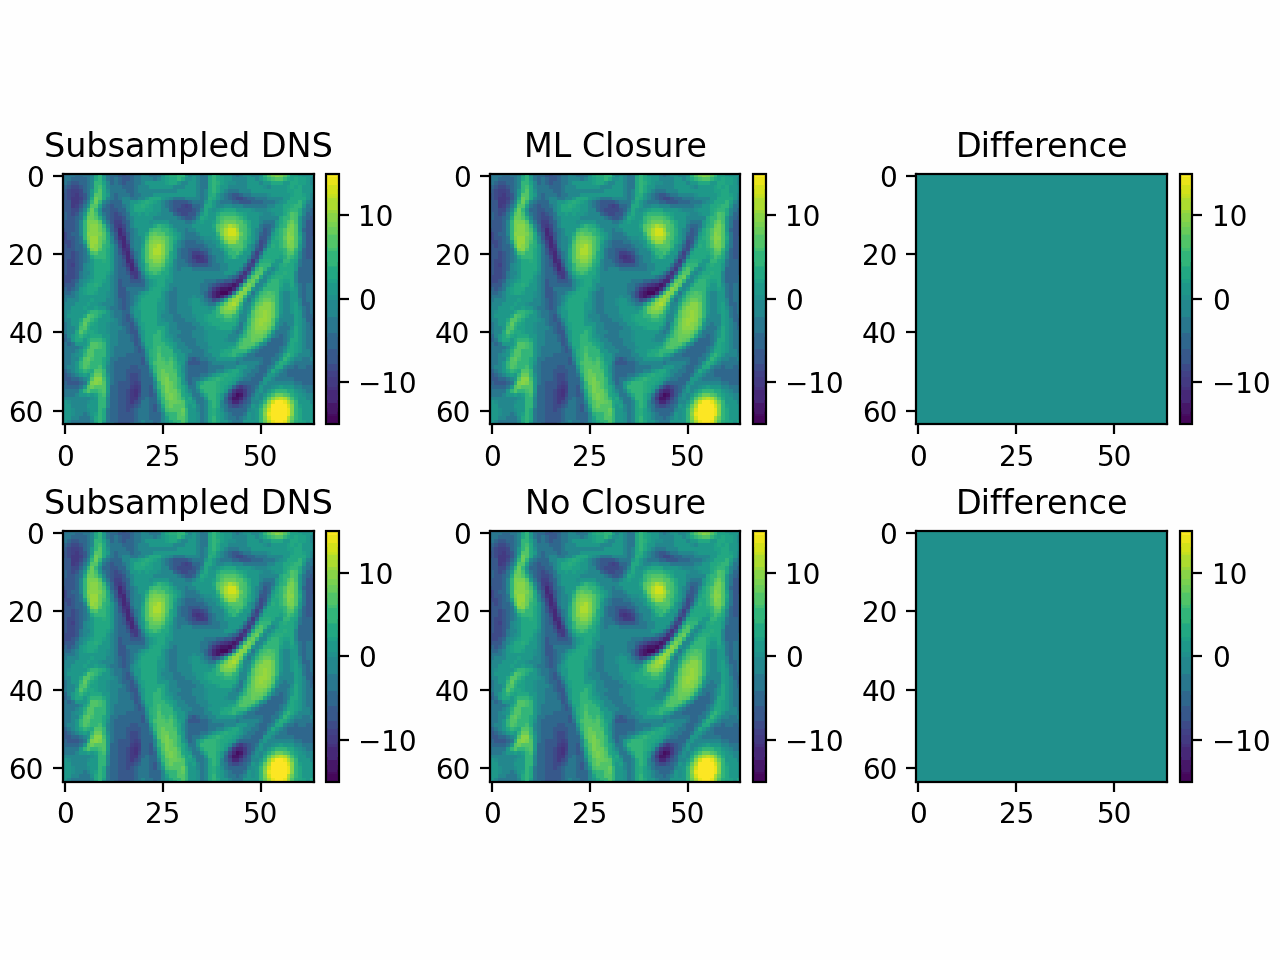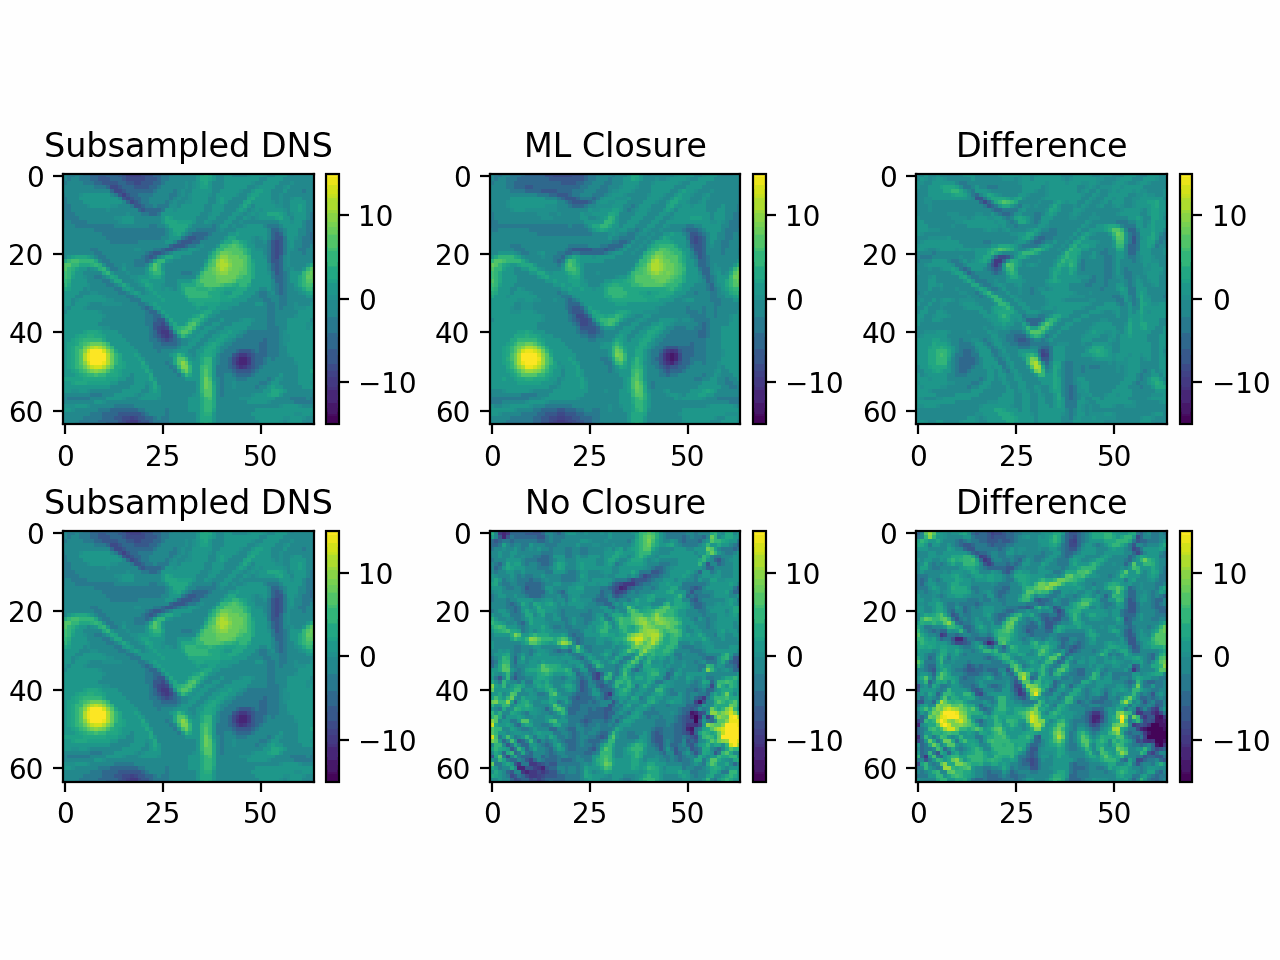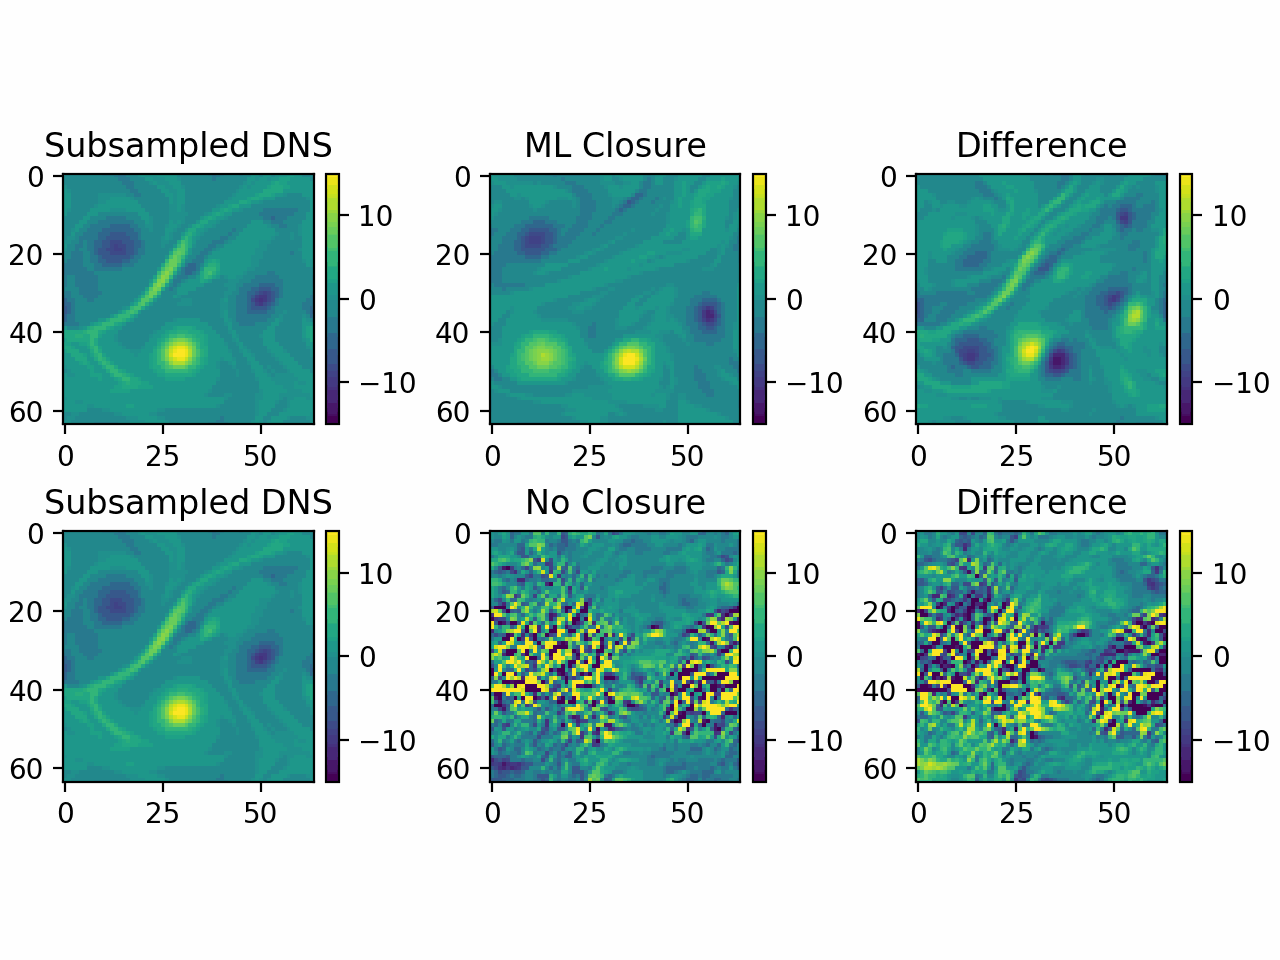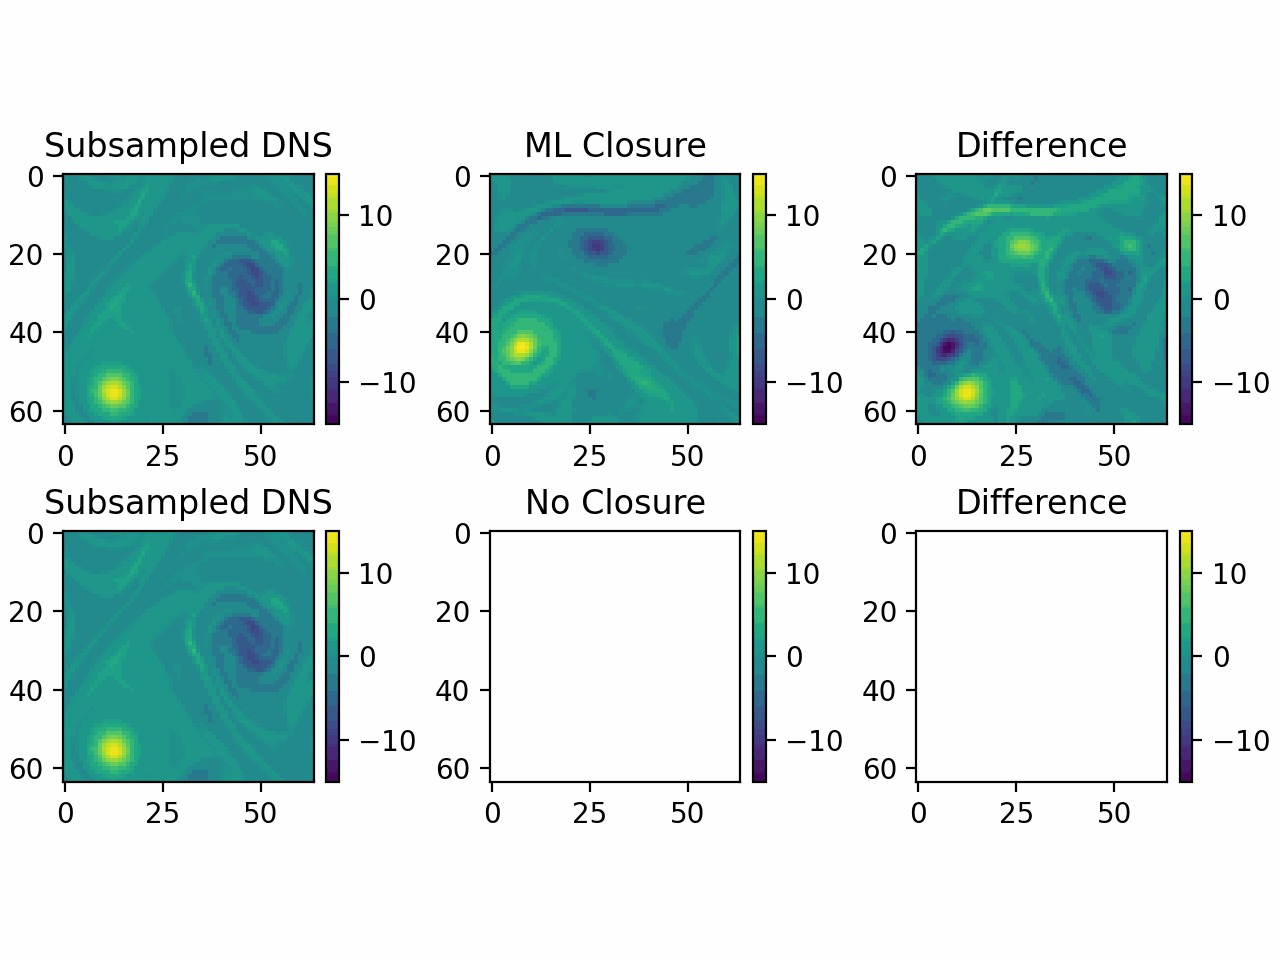
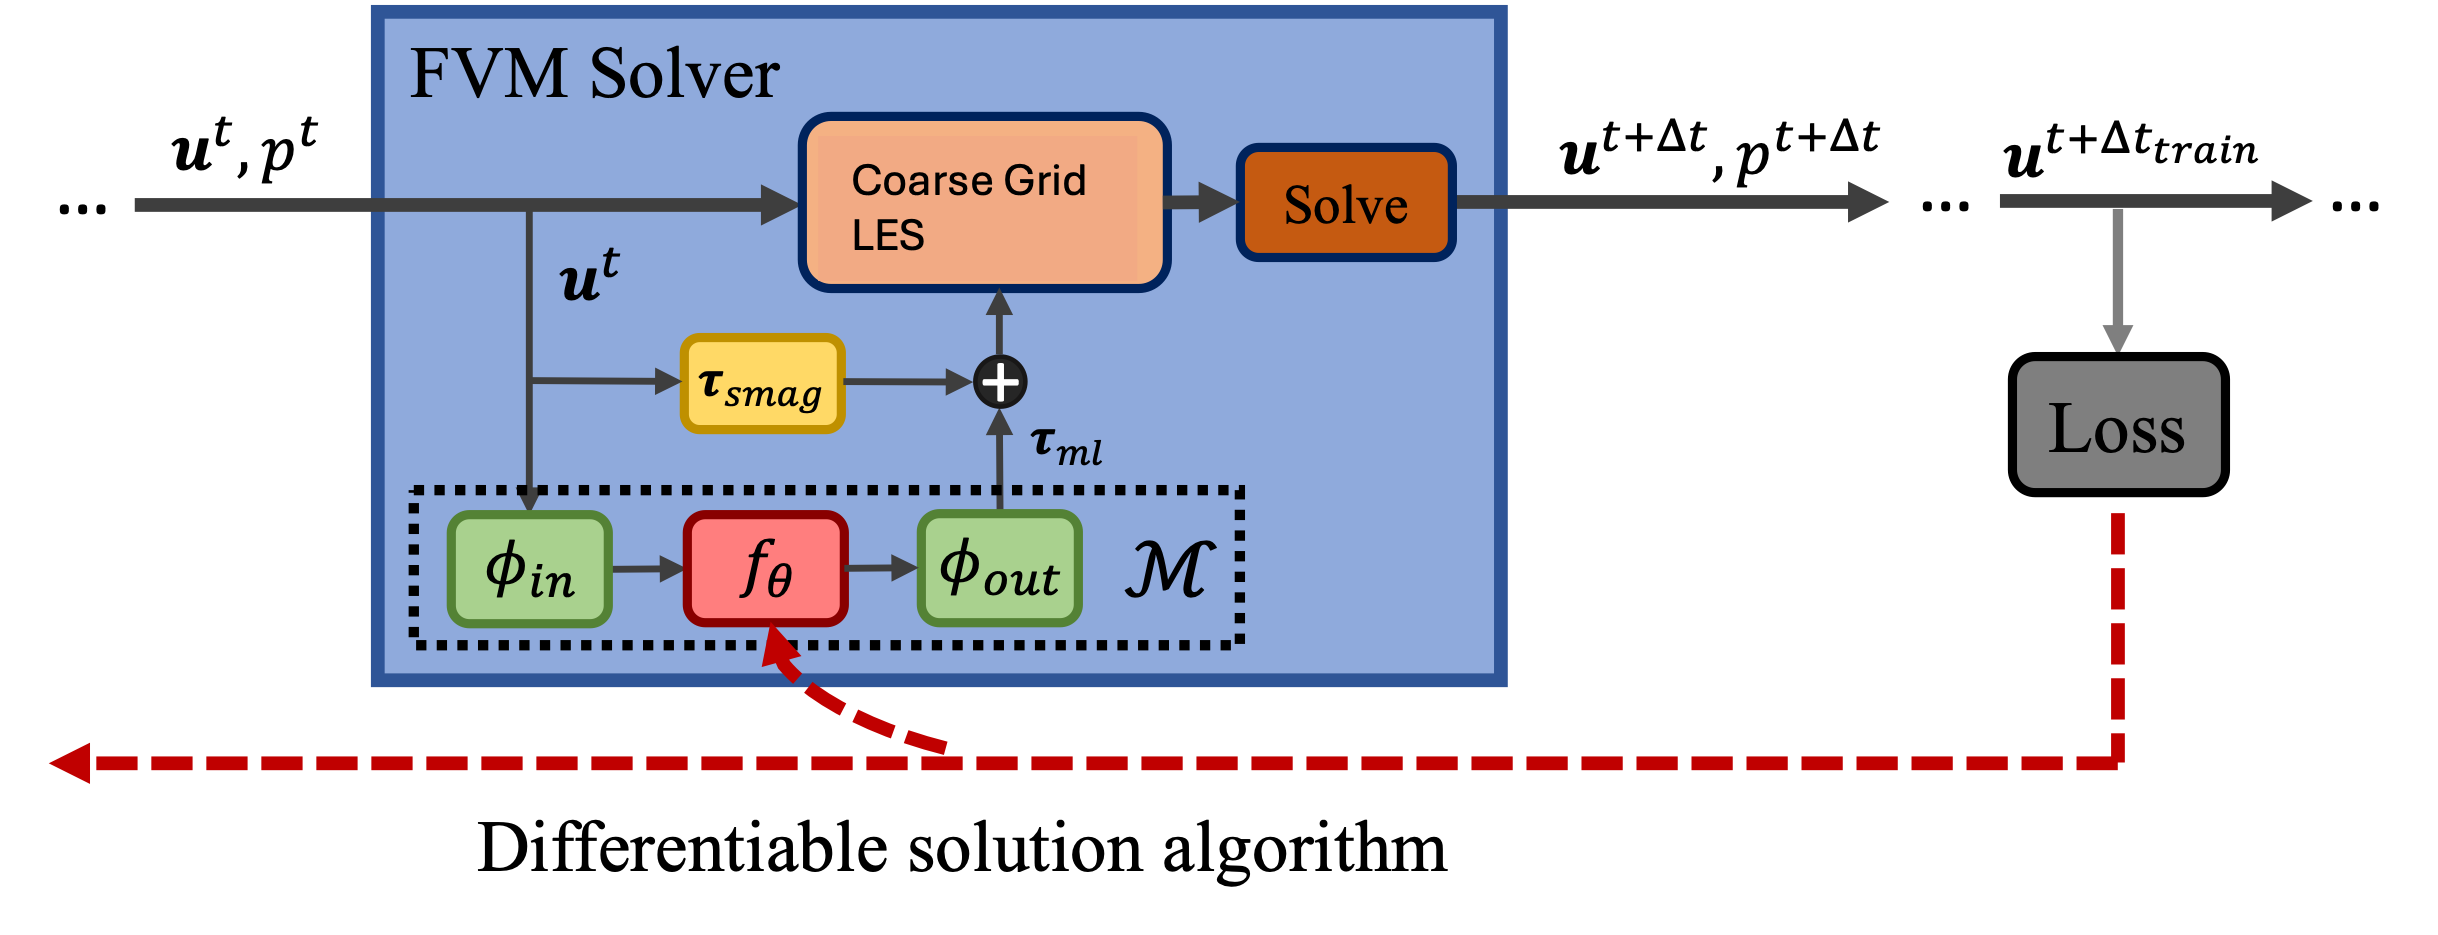
The paper addresses the challenge of learning subgrid-scale closures that remain useful
when embedded inside a turbulence solver, rather than only matching offline targets. It
uses an end-to-end differentiable LES setup with physics-inspired neural architectures for
two-dimensional turbulence.
The results show that small-scale nonlocal information is especially important for SGS
modeling, while larger-scale features improve pointwise accuracy. The broader conclusion
is that differentiable solver-in-the-loop training can produce closures that generalize
across Reynolds numbers and forcing conditions, with uncertainty quantified through
ensembles.
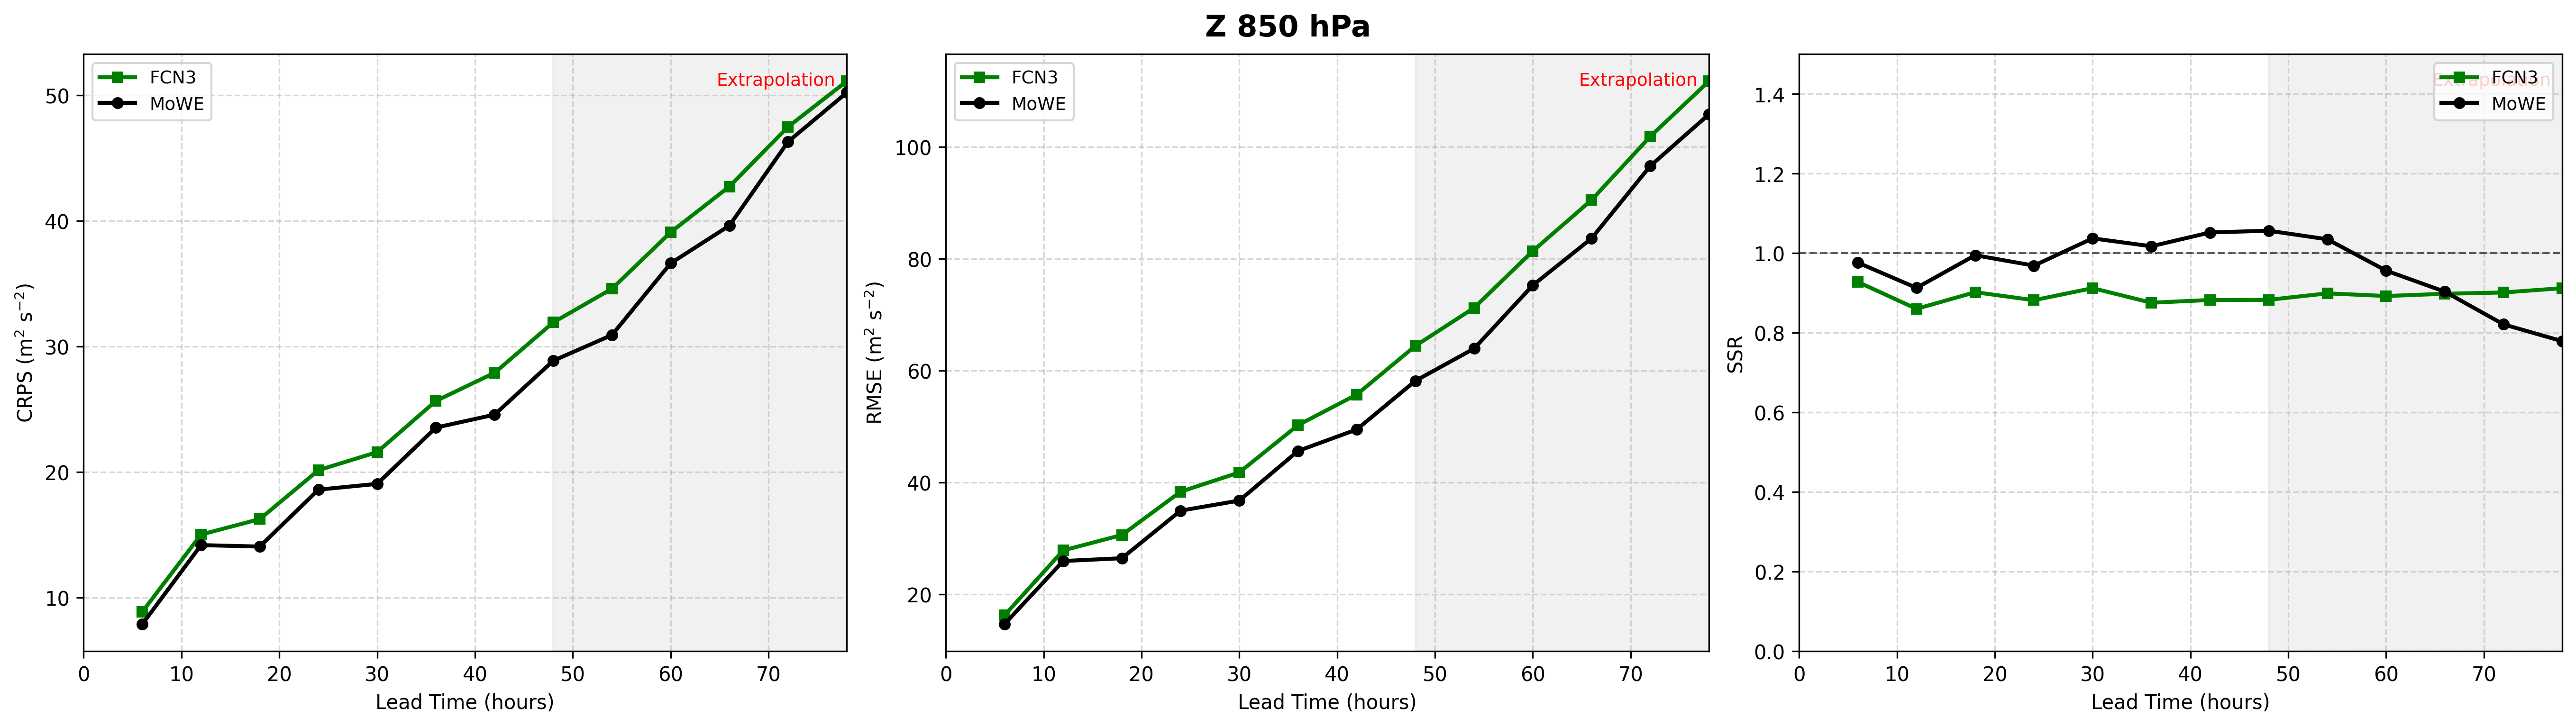
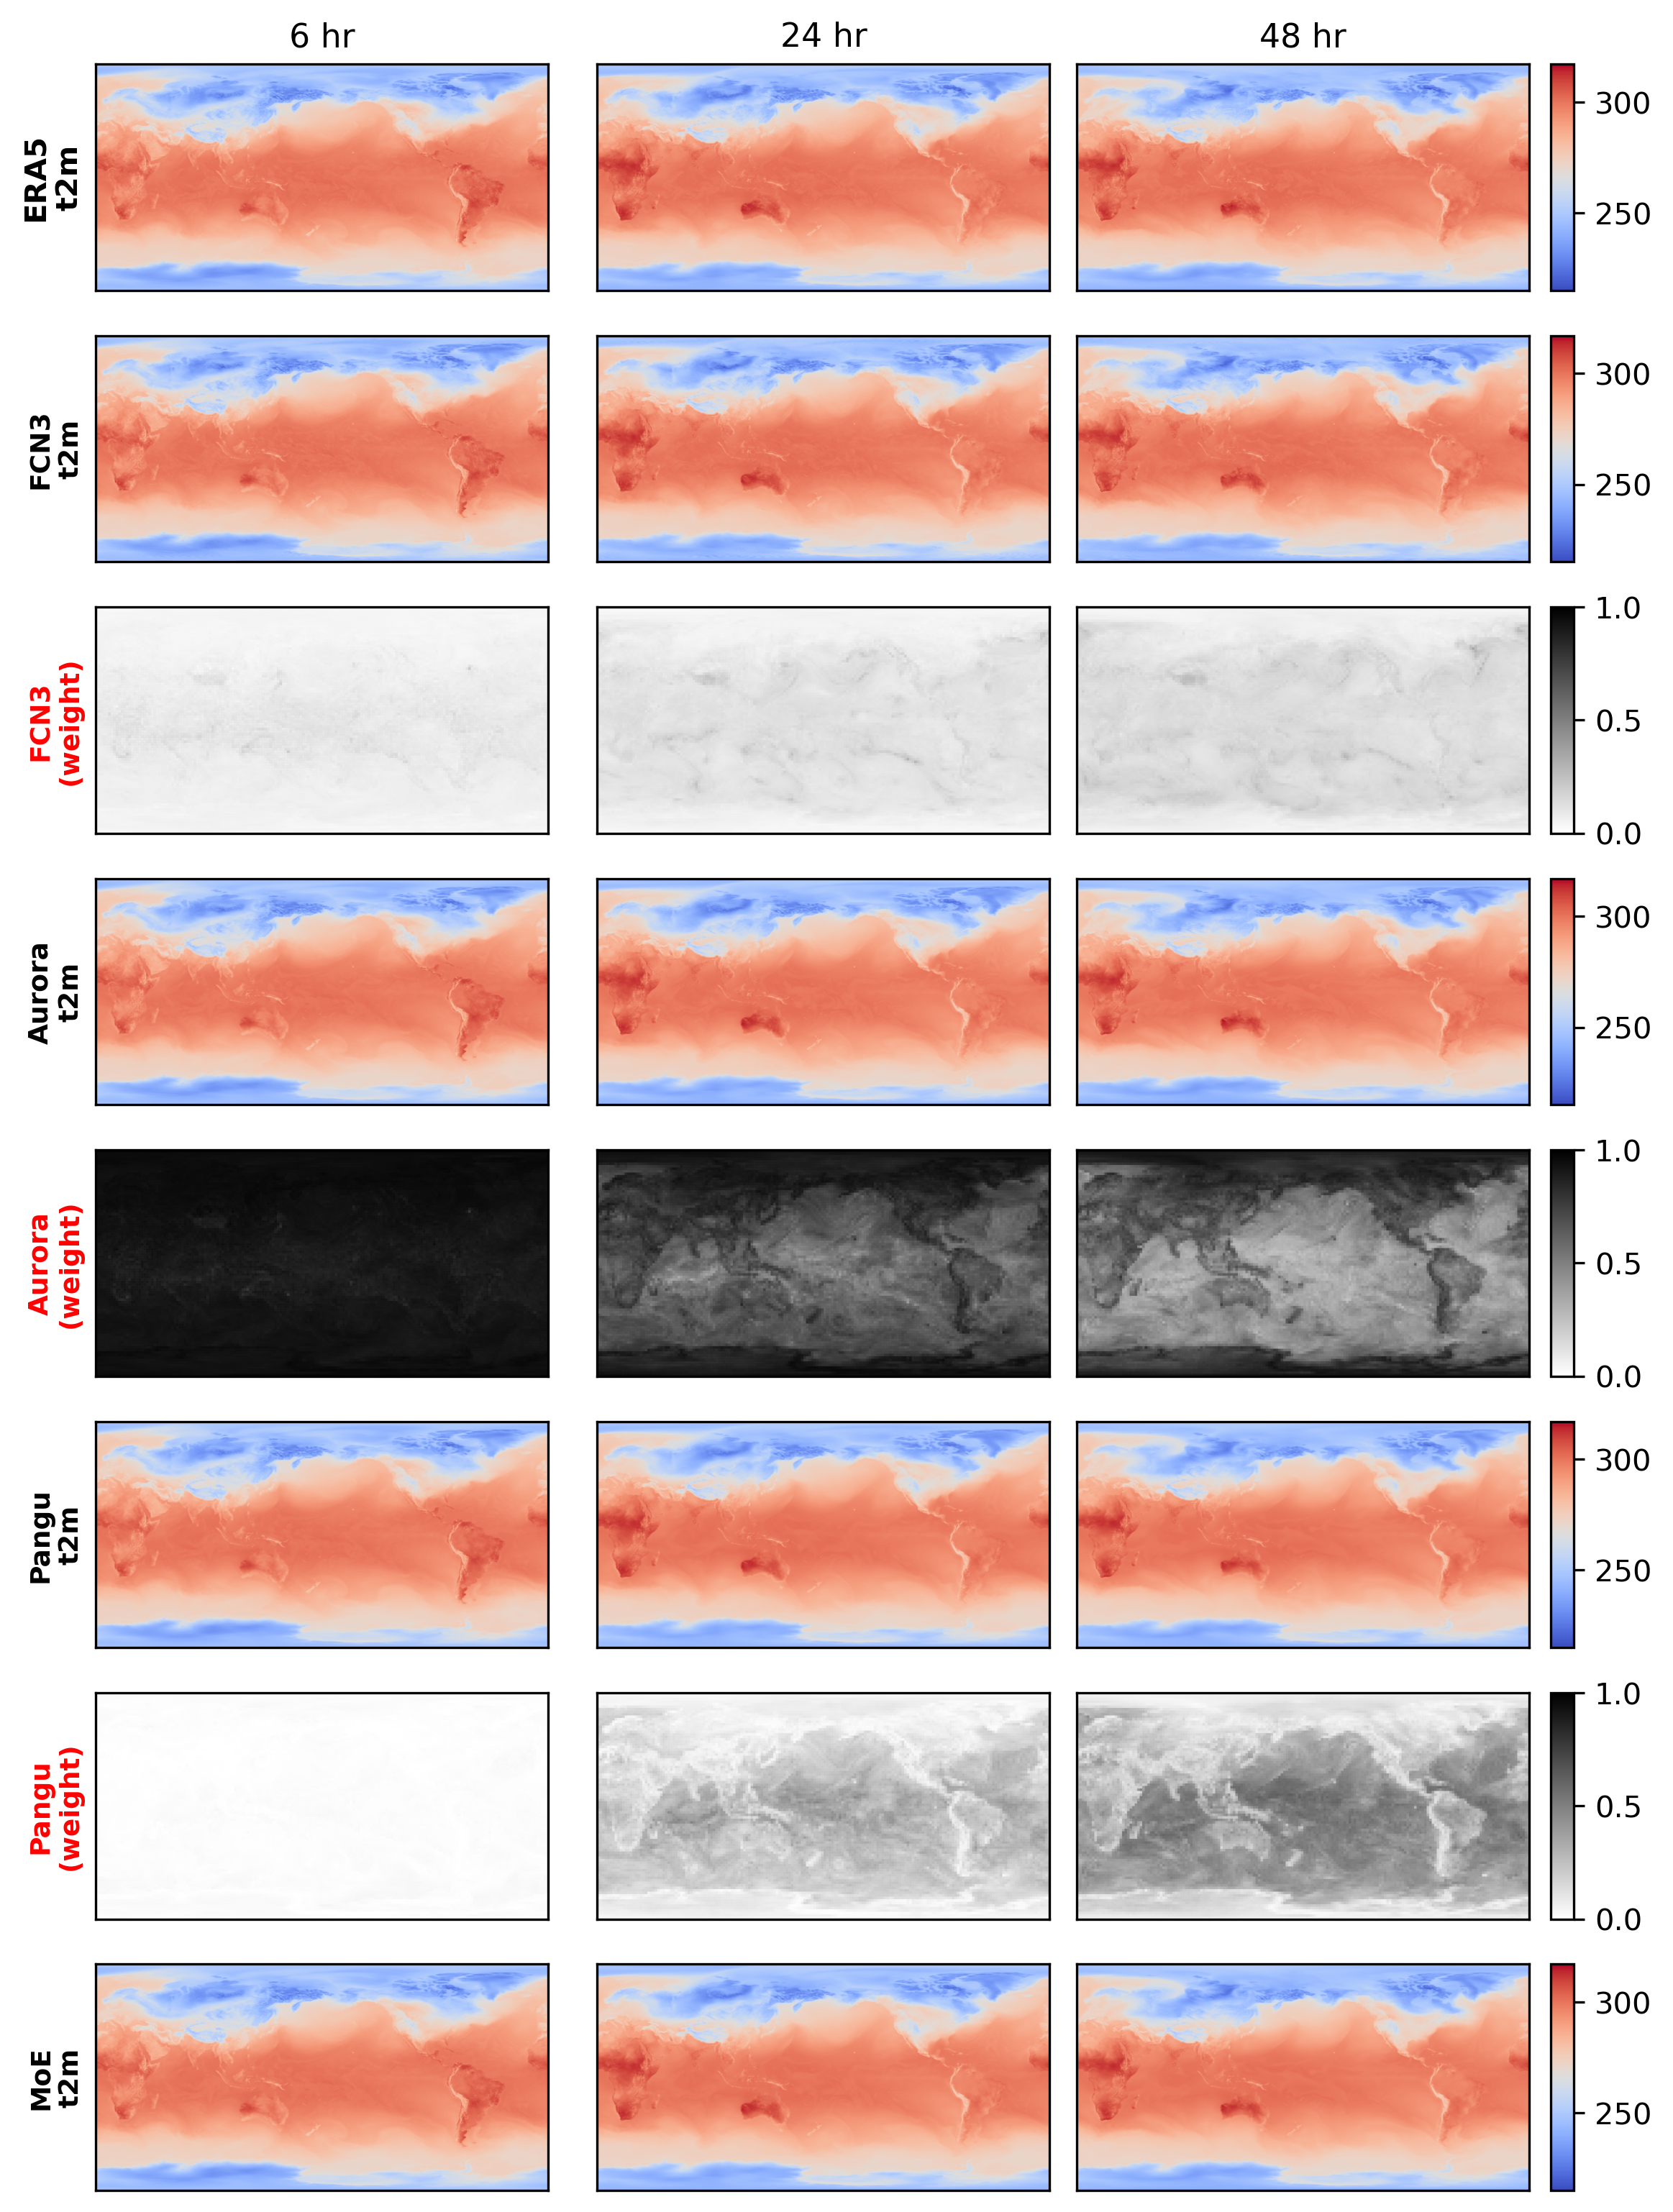
MoWE introduces a mixture-of-experts framework that does not train a completely new
forecaster from scratch. Instead, it combines the outputs of existing weather models
using a Vision Transformer-based gating network that learns weights at each grid point.
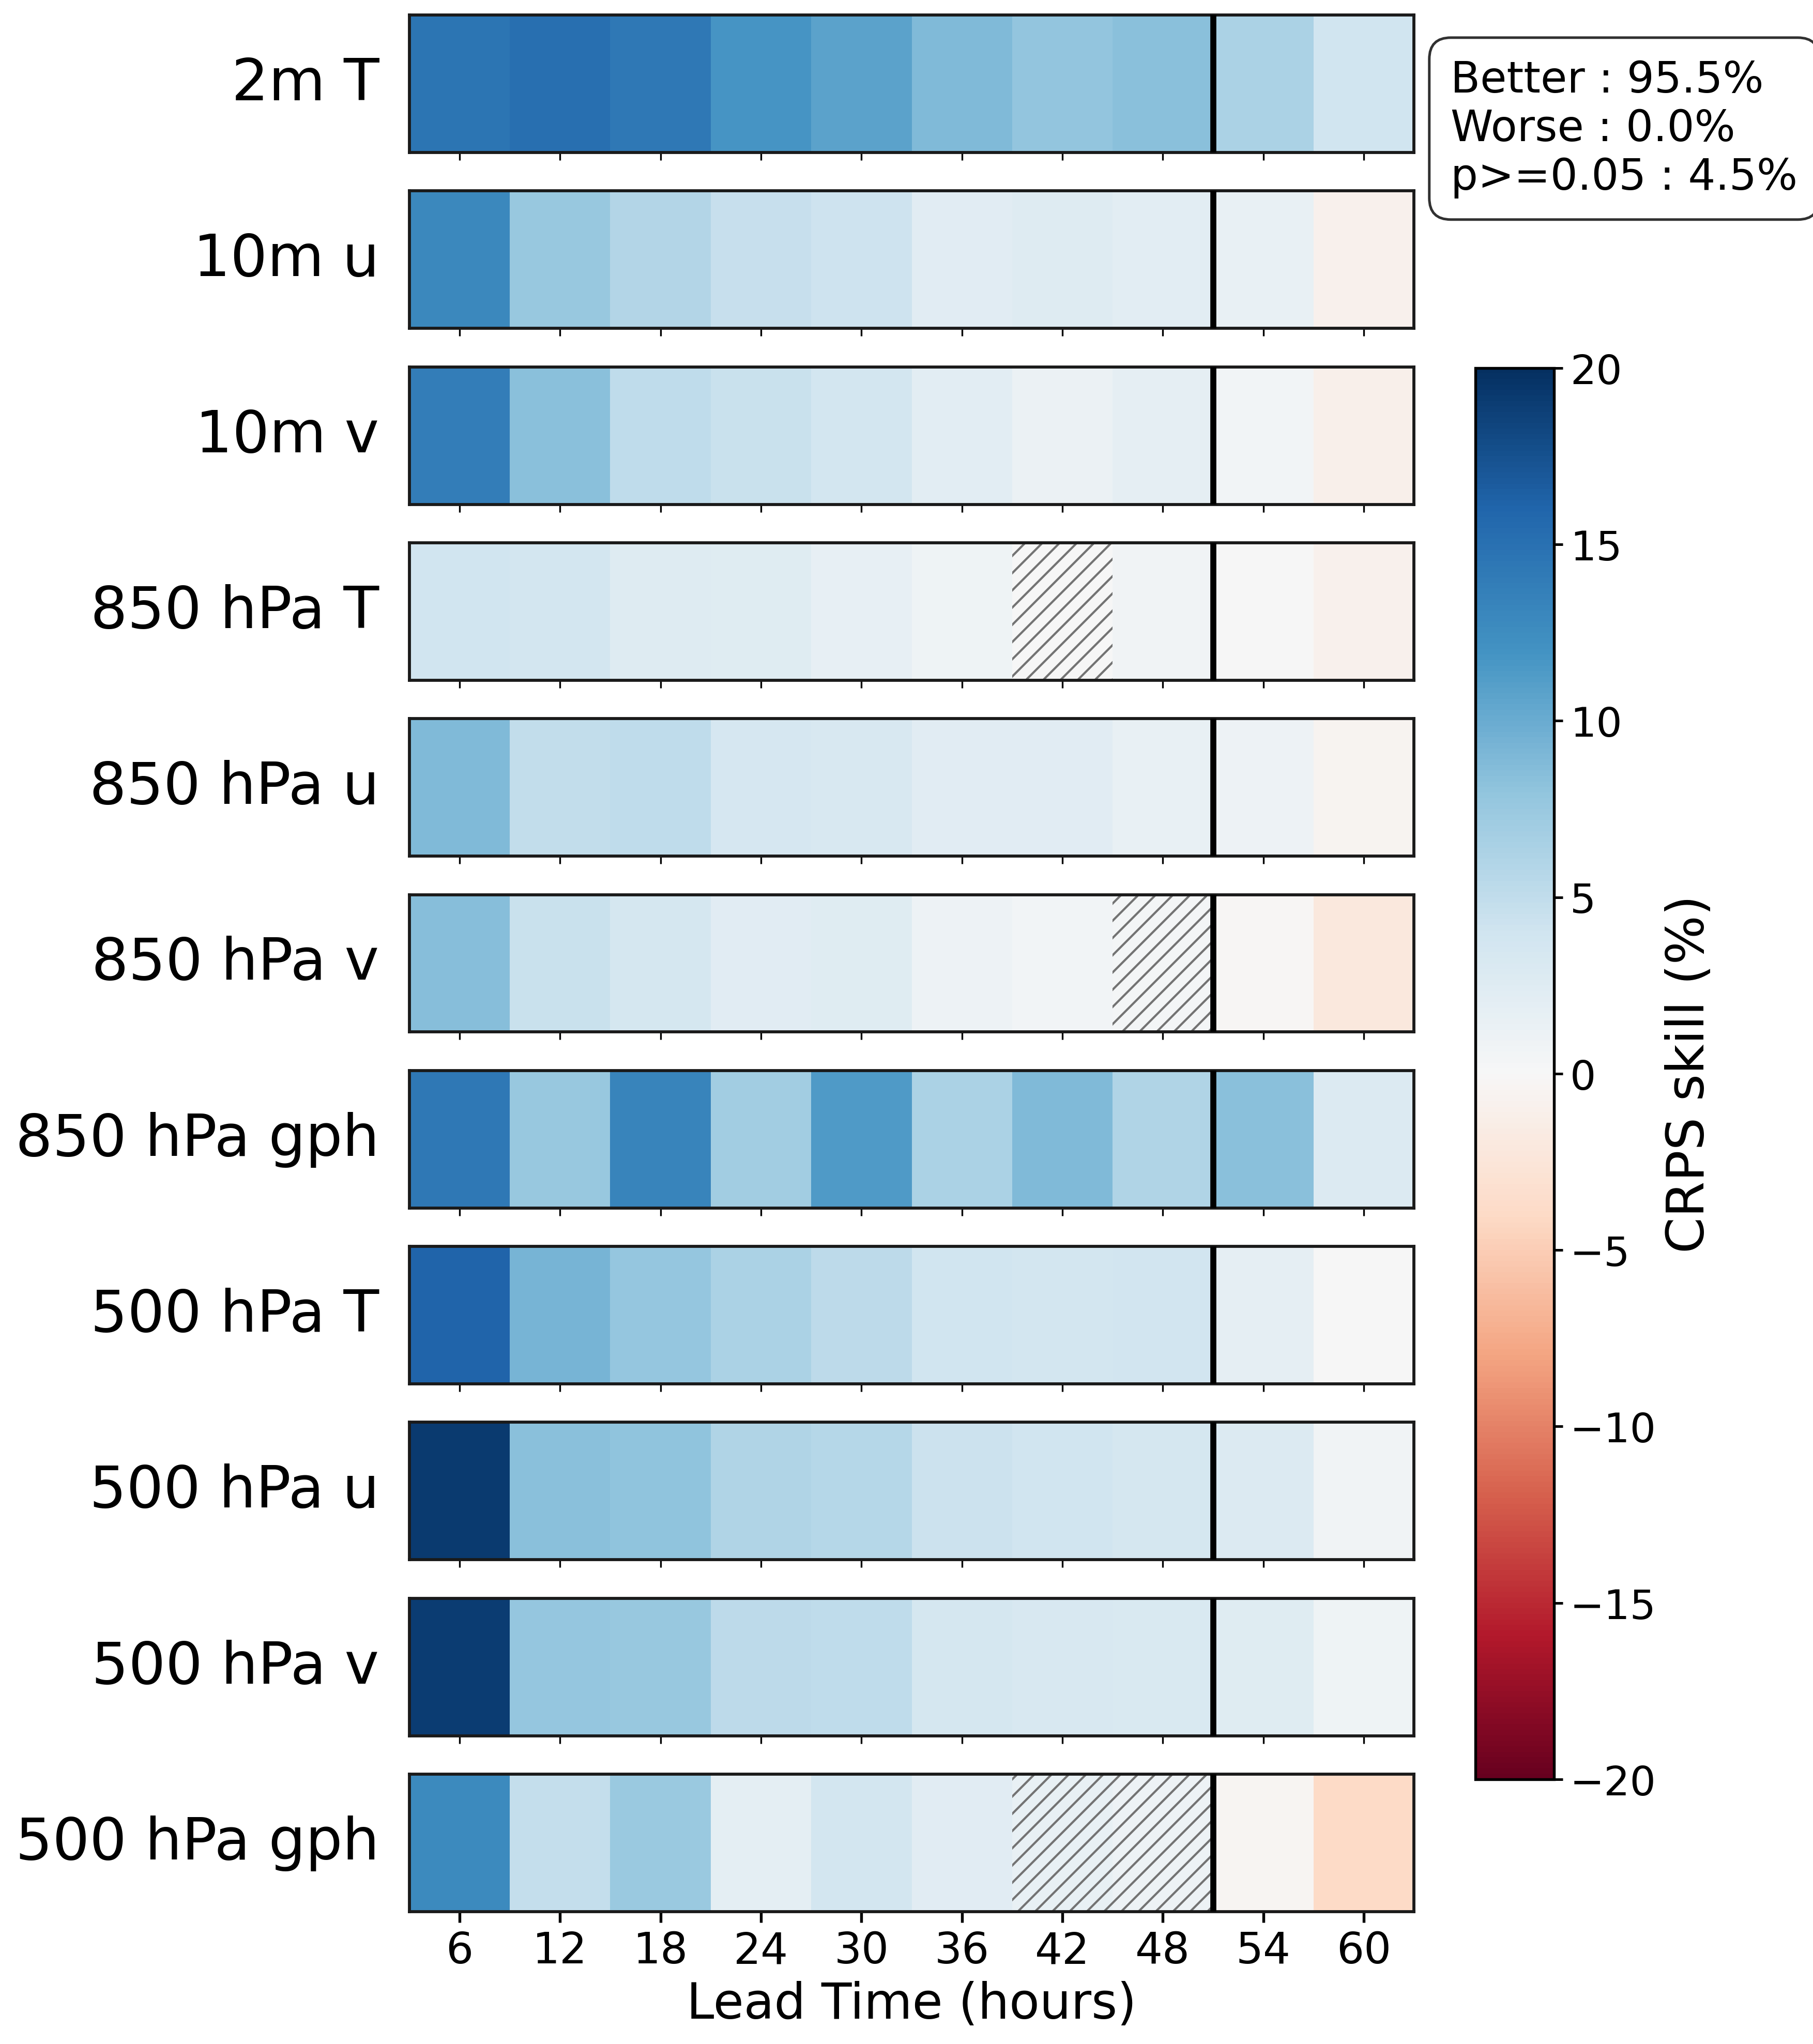
The results show a deterministic forecast that outperforms any individual expert in RMSE,
with the paper reporting improvements of up to about 10% over the strongest AI weather
model at a two-day lead time. The main conclusion is that intelligently combining strong
existing models can be both more accurate and more compute-efficient than retraining a new
large weather model from scratch.
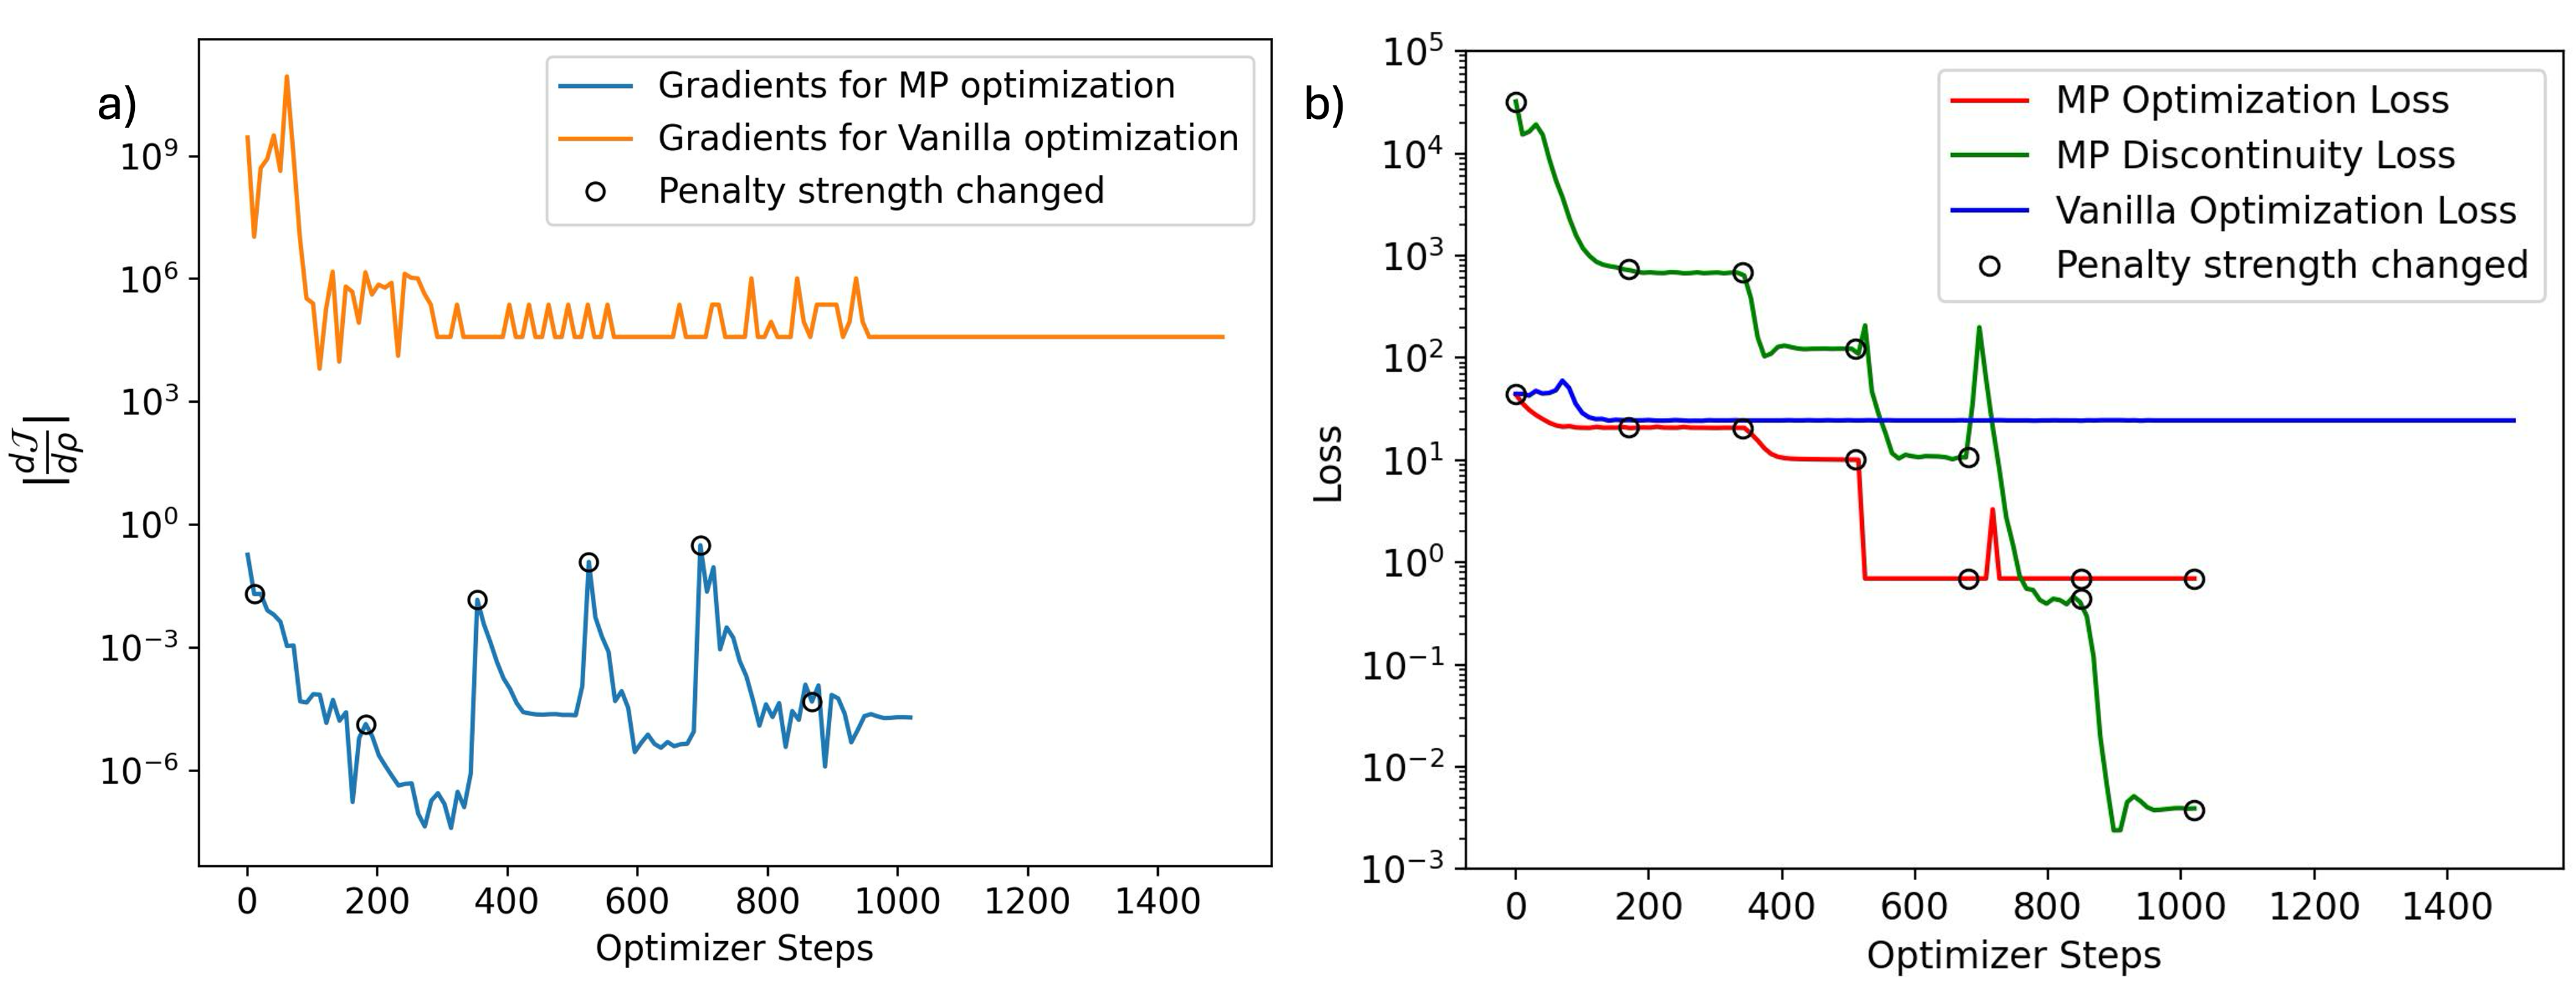
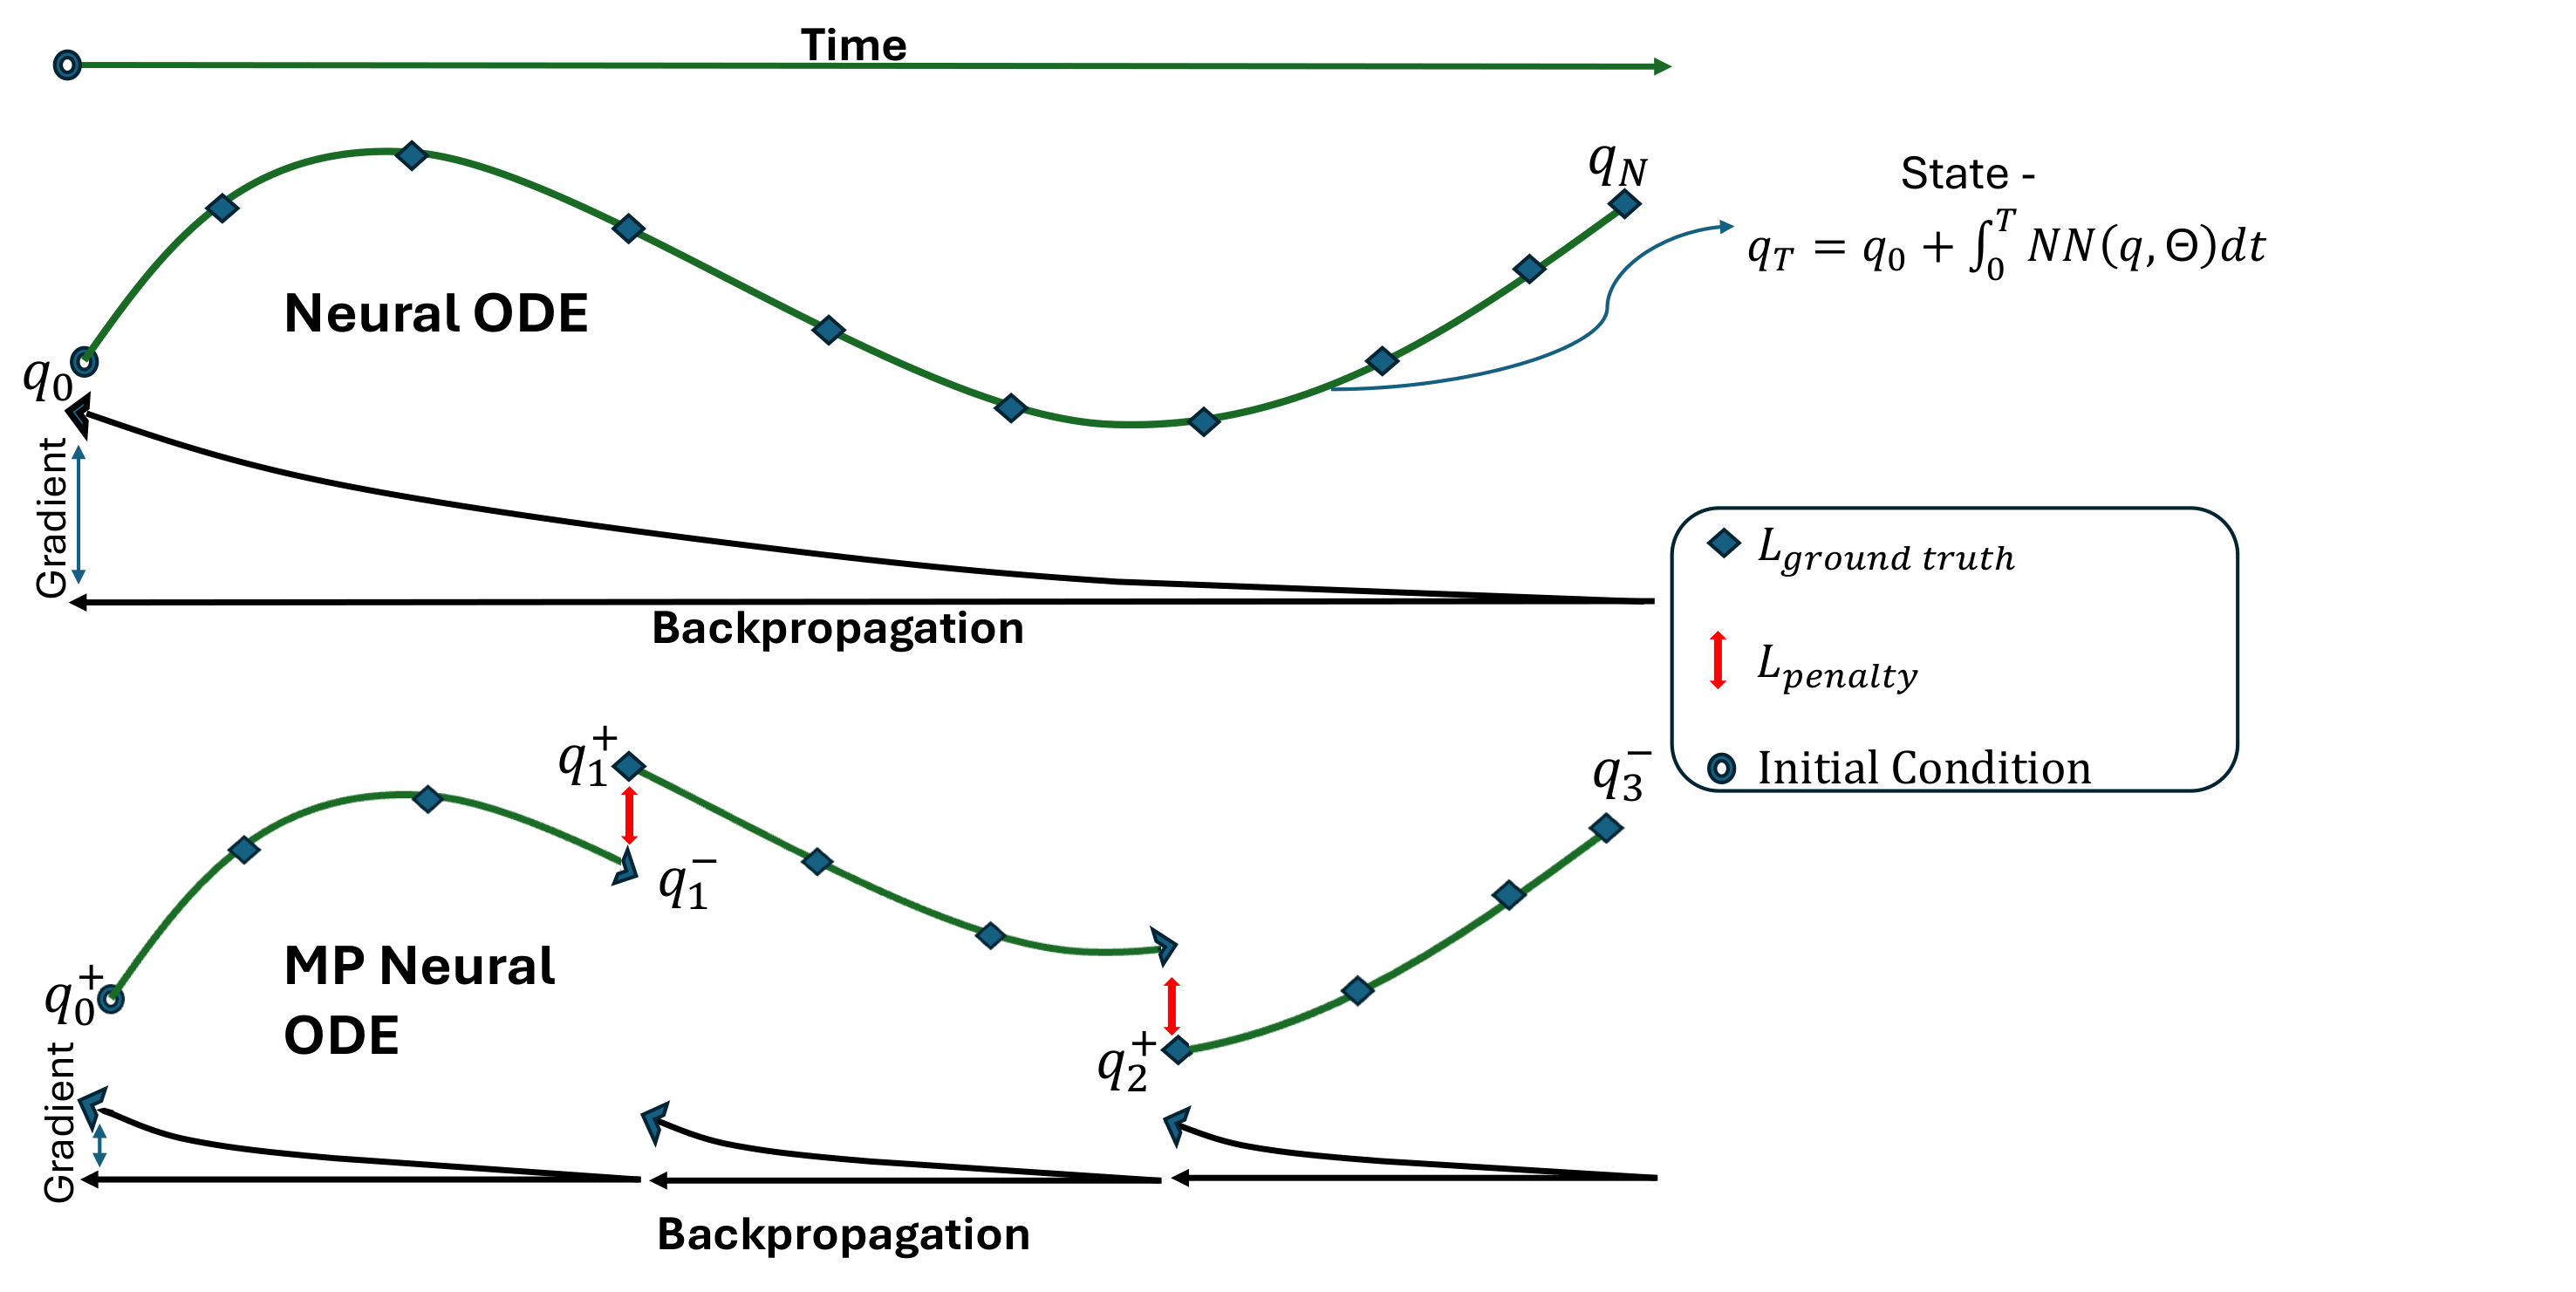
Chaotic dynamics are notoriously hard to learn with neural ODEs because training becomes
highly non-convex and gradients can grow unstable over long trajectories. This paper
addresses that by breaking trajectories into non-overlapping windows and penalizing
discontinuities between predicted segments.
The method is evaluated on Lorenz, Kuramoto-Sivashinsky, Kolmogorov flow, and ERA5
atmosphere data, where it delivers reliable short-term forecasts together with improved
invariant statistics. The conclusion is that trajectory windowing and multistep penalties
make NODE training substantially more practical for chaotic systems.